So let’s figure out what exactly the ELK stack is
The ELK stack is an abbreviation for Elasticsearch, Logstash, and Kibana, which offers the following capabilities:
- Elasticsearch: a distributed search and analytics engine. It stores your logs and makes them searchable in near real time.
- Logstash: a log-processing tool that collects logs from various sources, parses them, and sends them to Elasticsearch for storage and analysis.
- Kibana: A powerful visualization tool that allows you to explore and analyze the data stored in Elasticsearch using interactive charts, graphs, and dashboards.
- Beats: lightweight shippers that send data to Logstash or Elasticsearch. Filebeat is the one for log files. Elastic calls the whole set (Elasticsearch, Kibana, Beats, and Logstash) the Elastic Stack, also known as the ELK stack.
The architecture of Elasticsearch
Before we dive into deploying the ELK Stack, let's first understand the critical components of Elasticsearch's infrastructure:
- Nodes: a node is a running instance of Elasticsearch. Several nodes together form a cluster. On Kubernetes, each node is a Pod.
- Shards: each index is split into shards, so data can be spread across nodes and searched in parallel. Replica shards are copies that keep data available when a node fails.
- Indices: Elasticsearch organizes the stored data into indices. Logs usually go into data streams, which write to a series of hidden backing indices and roll over to a new one automatically.
What you need
You'll need a Kubernetes cluster to deploy the ELK Stack on Kubernetes. If you already have one, you can proceed with the deployment. On AWS, the community terraform-aws-eks module is a quick way to create an EKS cluster with Terraform.
You'll also need kubectl and Helm 3.2 or newer on your machine. ECK 3.5 supports Kubernetes 1.31 to 1.36, including EKS, GKE, AKS, and OpenShift 4.16 to 4.22.
Plan for memory. If you don't set resources, ECK applies these defaults:
- Elasticsearch: 2Gi per node
- Kibana: 2Gi
- Logstash: 2Gi
- Filebeat: 300Mi on every Kubernetes node
So for this demo you need about 6Gi of free memory for Elasticsearch, Kibana, and Logstash, plus up to 1Gi for the operator and 300Mi of Filebeat on each node. If no node has 2Gi of free memory, the Elasticsearch Pod stays Pending.
Why ECK and not Helm charts
Many tutorials still install Elasticsearch and Kibana with the elastic/elasticsearch and elastic/kibana Helm charts. Elastic archived that repository on May 16, 2023, and its last release is 8.5.1, so it gets no new versions or fixes. Elastic itself recommends Elastic Cloud on Kubernetes (ECK) as the way to run the stack on Kubernetes.
ECK is an operator. You describe Elasticsearch, Kibana, Logstash, and Filebeat as Kubernetes resources, and it handles the rest: TLS certificates, the elastic user and its password, service accounts between components, rolling upgrades, and scaling. ECK with the Basic license is free.
You still use Helm, just for the operator. The chart is published in the Elastic Helm repository and listed on Artifact Hub.
Install the ECK operator
Add the Elastic Helm repository and install the operator into its own namespace:
shell
1helm repo add elastic https://helm.elastic.co2helm repo update3helm install elastic-operator elastic/eck-operator -n elastic-system --create-namespaceCheck that the operator Pod is running, then create a namespace for the stack itself:
shell
1kubectl get pods -n elastic-system2kubectl create namespace elastic-stackAll commands below use the elastic-stack namespace.
Deploy Elasticsearch
Save this manifest as elasticsearch.yaml. It's the single-node cluster from the ECK quickstart:
yaml
1apiVersion: elasticsearch.k8s.elastic.co/v12kind: Elasticsearch3metadata:4 name: quickstart5spec:6 version: 9.5.57 nodeSets:8 - name: default9 count: 110 config:11 node.store.allow_mmap: falseApply it and watch the status. The cluster is ready when HEALTH is green and PHASE is Ready:
shell
1kubectl apply -f elasticsearch.yaml -n elastic-stack2kubectl get elasticsearch -n elastic-stackECK creates the elastic user and stores its password in the quickstart-es-elastic-user Secret. It also enables HTTPS with a self-signed certificate and creates a ClusterIP Service called quickstart-es-http on port 9200.
⚠️ This is a demo setup: one node with no room for replica shards, and node.store.allow_mmap: false, which Elastic says has performance implications. For production, run at least three nodes, set the kernel setting vm.max_map_count to 1048576 on the hosts and remove the allow_mmap line, and set your own resources and volume size.
Note: Elasticsearch stores data on a PersistentVolume. The quickstart requests 1Gi from your cluster's default storage class, so make sure one exists (kubectl get storageclass). On EKS, install the Amazon EBS CSI driver add-on first, otherwise the volume isn't created and the Pod stays Pending. EBS is the usual choice for Elasticsearch data. EFS is a network file system, which fits shared files like snapshot repositories better than live indices.
Deploying Kibana
With ECK, Kibana is one more resource. The elasticsearchRef field points it at the cluster, and the operator sets up the URL, credentials, and certificates for you. Save this as kibana.yaml:
yaml
1apiVersion: kibana.k8s.elastic.co/v12kind: Kibana3metadata:4 name: quickstart5spec:6 version: 9.5.57 count: 18 elasticsearchRef:9 name: quickstartApply it and check the status:
shell
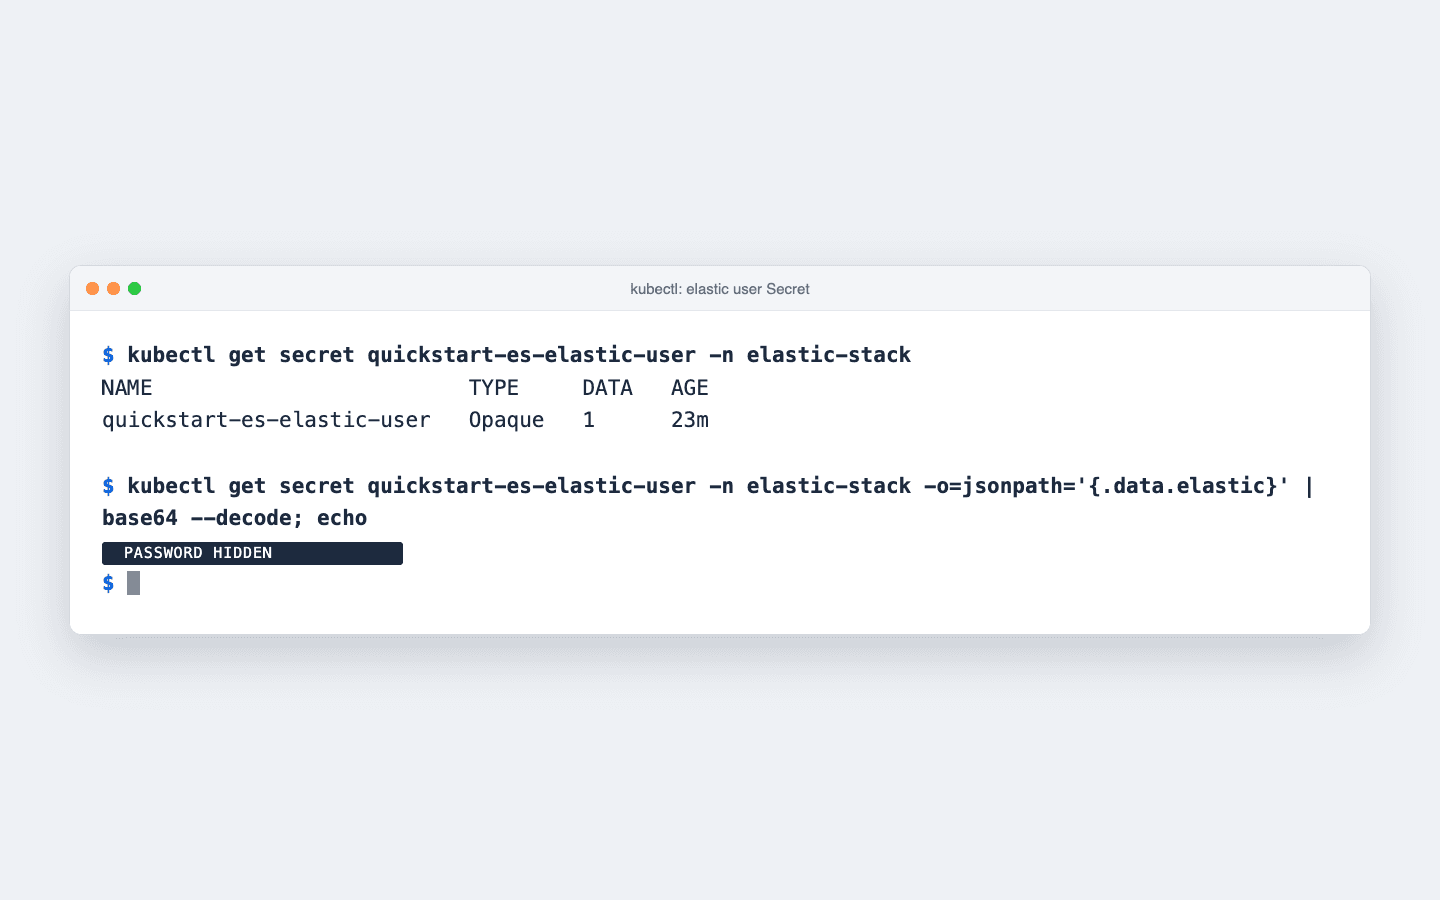
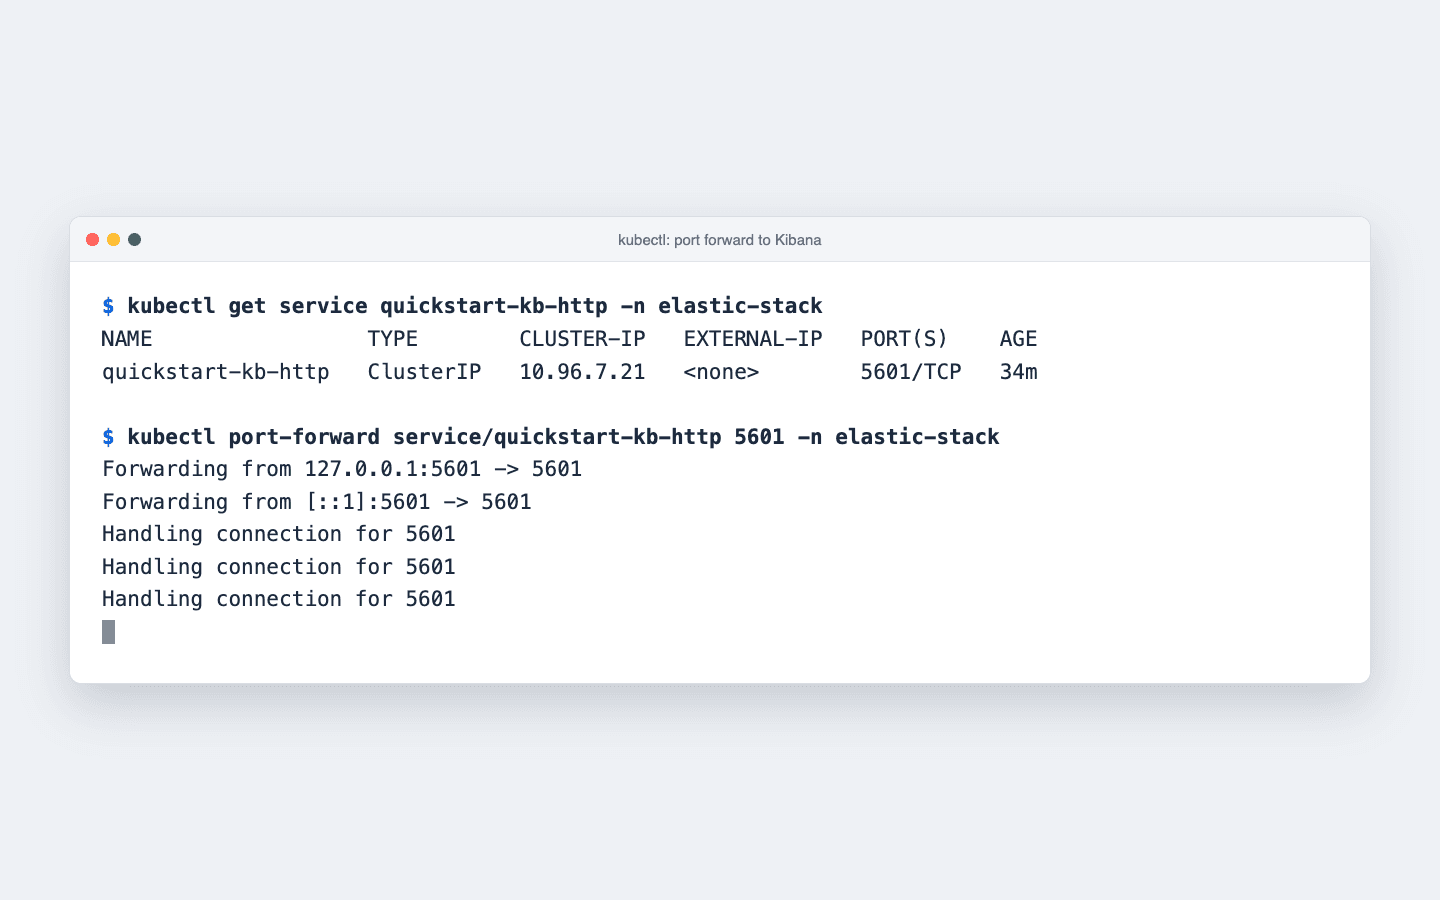
1kubectl apply -f kibana.yaml -n elastic-stack2kubectl get kibana -n elastic-stackCheck if Kibana is installed correctly by port forwarding its Service to your machine. First, get the password of the elastic user, then start the port forward:
shell
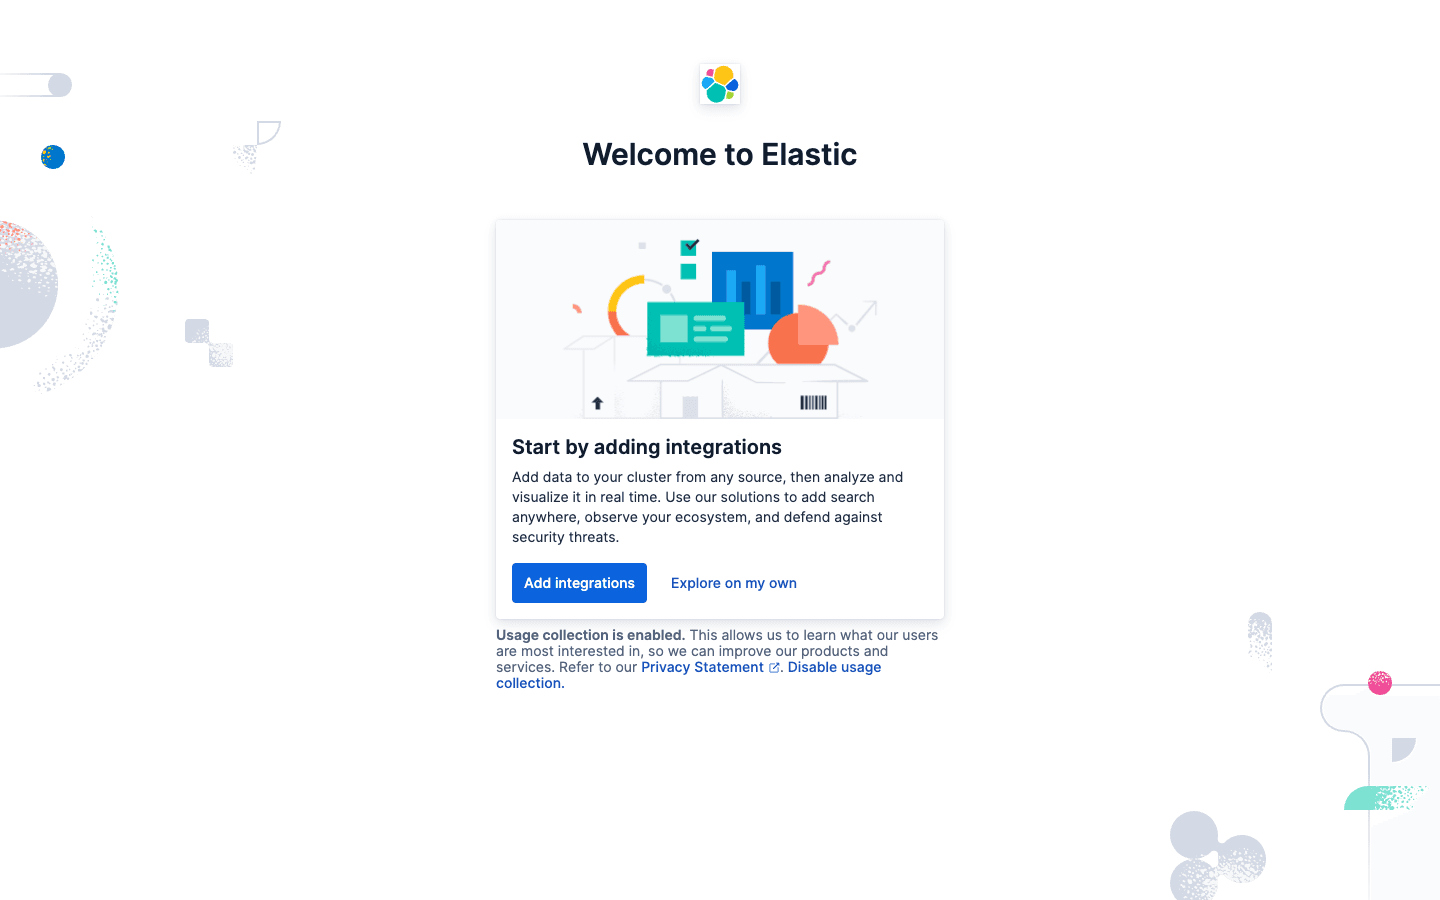
1kubectl get secret quickstart-es-elastic-user -n elastic-stack -o=jsonpath='{.data.elastic}' | base64 --decode; echo2kubectl port-forward service/quickstart-kb-http 5601 -n elastic-stackOpen https://localhost:5601 and log in as elastic. The browser will warn you about the certificate because ECK uses a self-signed one by default. That's fine for a test; for production, configure a valid certificate.
You can do the same in a GUI like Lens. Here's what the terminal and the first Kibana screen look like on a fresh ECK cluster.
The quickstart-es-elastic-user Secret (password hidden)
Port forwarding to the quickstart-kb-http Service
Welcome to Elastic: the first screen after login
Deploying Logstash and Filebeat
To manage logs effectively, we use Logstash and Filebeat. Filebeat collects records from various sources and Logstash processes and sends them to Elasticsearch.
Do you actually need Logstash? Not always. Filebeat (or Elastic Agent) can send logs straight to Elasticsearch, and ingest pipelines in Elasticsearch can handle most parsing. Logstash earns its place when you need heavier processing: grok and other filters, enrichment, sending the same events to several outputs, inputs other than Beats, or a persistent queue that buffers events when Elasticsearch is slow. This guide keeps Logstash because it's the L in ELK, and we show how to skip it at the end of the Filebeat step.
Deploy Logstash:
Save this manifest as logstash.yaml. It's based on the ECK Logstash quickstart: a Beats input on port 5044 and an Elasticsearch output.
yaml
1apiVersion: logstash.k8s.elastic.co/v1alpha12kind: Logstash3metadata:4 name: quickstart5spec:6 count: 17 elasticsearchRefs:8 - name: quickstart9 clusterName: qs10 version: 9.5.511 pipelines:12 - pipeline.id: main13 config.string: |14 input {15 beats {16 port => 504417 }18 }19 output {20 elasticsearch {21 hosts => [ "${QS_ES_HOSTS}" ]22 user => "${QS_ES_USER}"23 password => "${QS_ES_PASSWORD}"24 ssl_certificate_authorities => "${QS_ES_SSL_CERTIFICATE_AUTHORITY}"25 }26 }27 services:28 - name: beats29 service:30 spec:31 type: ClusterIP32 ports:33 - port: 504434 name: "filebeat"35 protocol: TCP36 targetPort: 5044You don't need to copy hosts, users, or passwords from Secrets. ECK creates a Logstash user in Elasticsearch and passes the connection details as environment variables. Their prefix comes from clusterName: qs turns into QS_ES_HOSTS, QS_ES_USER, and so on. ECK also creates a Service called quickstart-ls-beats that Filebeat will send logs to.
Add your own filter { } block between input and output when you need parsing. Apply the manifest:
shell
1kubectl apply -f logstash.yaml -n elastic-stack2kubectl get logstash -n elastic-stackDeploy Filebeat
- Filebeat runs as a DaemonSet, one Pod per node, and reads container logs from the node's disk. Usually, in EKS, it's the
/var/log/containersdirectory, and the same goes for most other distributions. To check it, log in to one of your nodes and navigate to the/var/log/containersdirectory; if there are no files, find where your container runtime writes logs and change the hostPath volumes below. - Save the manifest below as
filebeat.yaml. It's the Filebeat autodiscover example from the ECK docs with one change: the output goes to Logstash instead of straight to Elasticsearch. Autodiscover adds Kubernetes metadata (namespace, Pod, and container names) to every log line, so you can filter by app in Kibana. The ServiceAccount and RBAC objects at the bottom let Filebeat read that metadata from the Kubernetes API.
yaml
1apiVersion: beat.k8s.elastic.co/v1beta12kind: Beat3metadata:4 name: quickstart5spec:6 type: filebeat7 version: 9.5.58 config:9 filebeat:10 autodiscover:11 providers:12 - type: kubernetes13 node: ${NODE_NAME}14 hints:15 enabled: true16 default_config:17 type: filestream18 id: kubernetes-container-logs-${data.kubernetes.pod.name}-${data.kubernetes.container.id}19 paths:20 - /var/log/containers/*${data.kubernetes.container.id}.log21 parsers:22 - container: {}23 prospector:24 scanner:25 fingerprint.enabled: true26 symlinks: true27 file_identity.fingerprint: {}28 processors:29 - add_cloud_metadata: {}30 - add_host_metadata: {}31 output.logstash:32 hosts: ["quickstart-ls-beats.elastic-stack.svc:5044"]33 daemonSet:34 podTemplate:35 spec:36 serviceAccountName: filebeat37 automountServiceAccountToken: true38 terminationGracePeriodSeconds: 3039 dnsPolicy: ClusterFirstWithHostNet40 hostNetwork: true41 containers:42 - name: filebeat43 securityContext:44 runAsUser: 045 volumeMounts:46 - name: varlogcontainers47 mountPath: /var/log/containers48 - name: varlogpods49 mountPath: /var/log/pods50 - name: varlibdockercontainers51 mountPath: /var/lib/docker/containers52 env:53 - name: NODE_NAME54 valueFrom:55 fieldRef:56 fieldPath: spec.nodeName57 volumes:58 - name: varlogcontainers59 hostPath:60 path: /var/log/containers61 - name: varlogpods62 hostPath:63 path: /var/log/pods64 - name: varlibdockercontainers65 hostPath:66 path: /var/lib/docker/containers67---68apiVersion: rbac.authorization.k8s.io/v169kind: ClusterRole70metadata:71 name: filebeat72rules:73- apiGroups: [""]74 resources:75 - namespaces76 - pods77 - nodes78 verbs:79 - get80 - watch81 - list82- apiGroups: ["apps"]83 resources:84 - replicasets85 verbs:86 - get87 - list88 - watch89- apiGroups: ["batch"]90 resources:91 - jobs92 verbs:93 - get94 - list95 - watch96---97apiVersion: v198kind: ServiceAccount99metadata:100 name: filebeat101 namespace: elastic-stack102---103apiVersion: rbac.authorization.k8s.io/v1104kind: ClusterRoleBinding105metadata:106 name: filebeat107subjects:108- kind: ServiceAccount109 name: filebeat110 namespace: elastic-stack111roleRef:112 kind: ClusterRole113 name: filebeat114 apiGroup: rbac.authorization.k8s.ioIn case everything is correct, apply the manifest and check that a Filebeat Pod is running on every node:
shell
1kubectl apply -f filebeat.yaml -n elastic-stack2kubectl get beat -n elastic-stackWant to skip Logstash? Remove the output.logstash lines and add elasticsearchRef with name: quickstart under spec, like in the ECK Beats quickstart. Filebeat then writes straight to Elasticsearch, into the filebeat-* data stream, and you can use filebeat-* as the index pattern later.
The traffic between Filebeat and Logstash in this demo isn't encrypted. It stays inside the cluster, but for production enable SSL on the Beats input.
Deploy a simple application
To check how logs are streaming into Elasticsearch perform the following:
- Run the counter Pod from the Kubernetes logging docs. It prints a numbered line with the current date every second.
- Execute command:
shell
1kubectl apply -f https://k8s.io/examples/debug/counter-pod.yaml -n default2kubectl logs counter -n defaultAfter installation is complete, revisit Kibana. You don't need to create an Elasticsearch index by hand: Logstash creates the target on the first event. What you need in Kibana is a data view, which tells Kibana where to look.
Open Discover in Kibana
Open the main menu and select Discover under Analytics:
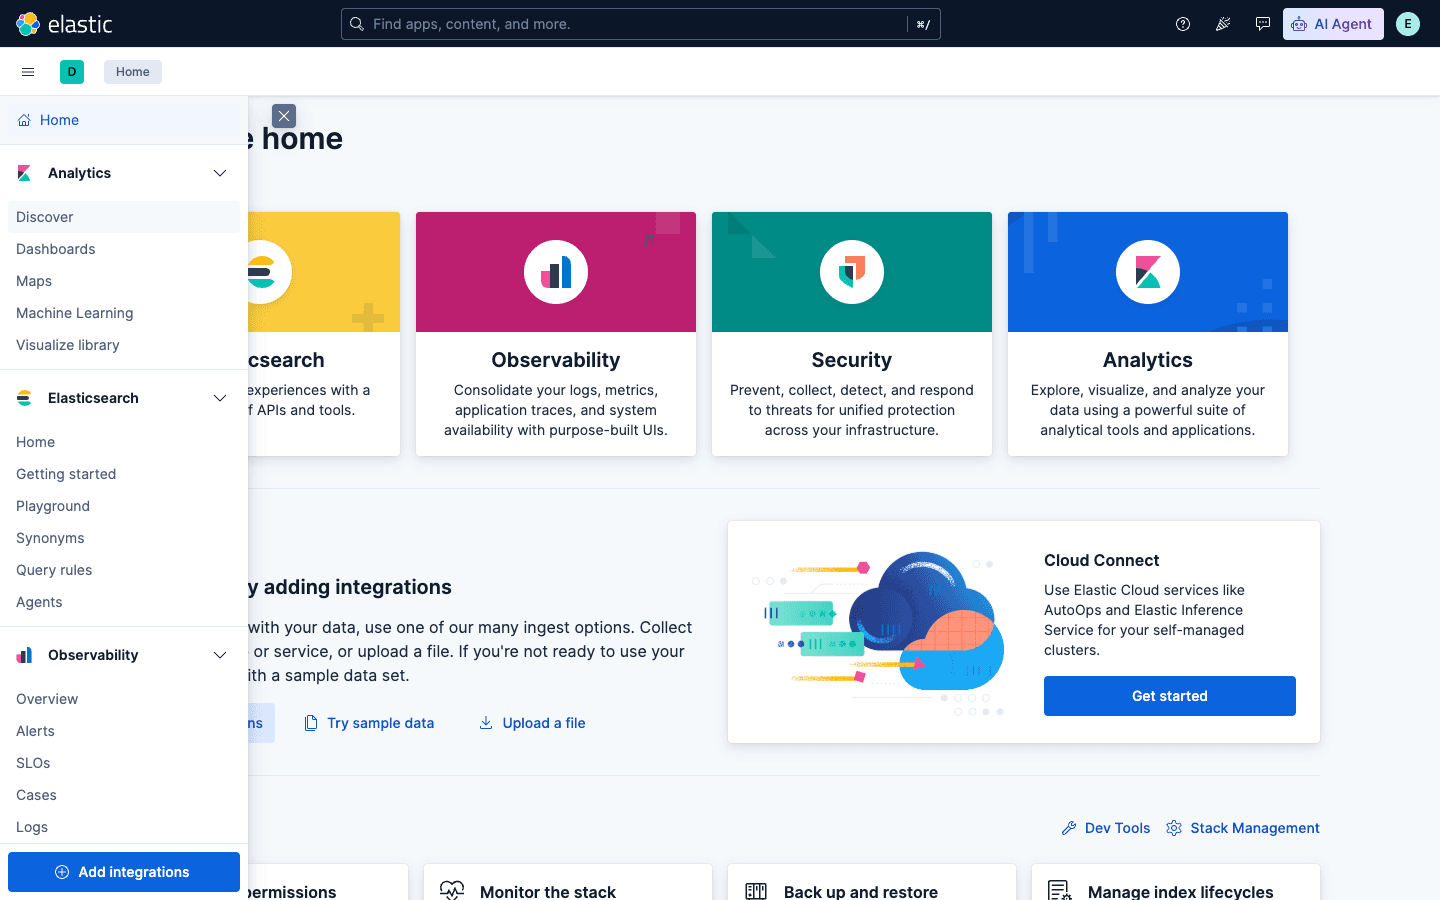
Data in Elasticsearch. Kibana 9.5 opens Discover with a built-in All logs data view, so you can see the events before you create your own:

Create a data view for Logstash logs
In Kibana 8 and 9, this step is called creating a data view. Older versions called it an index pattern.
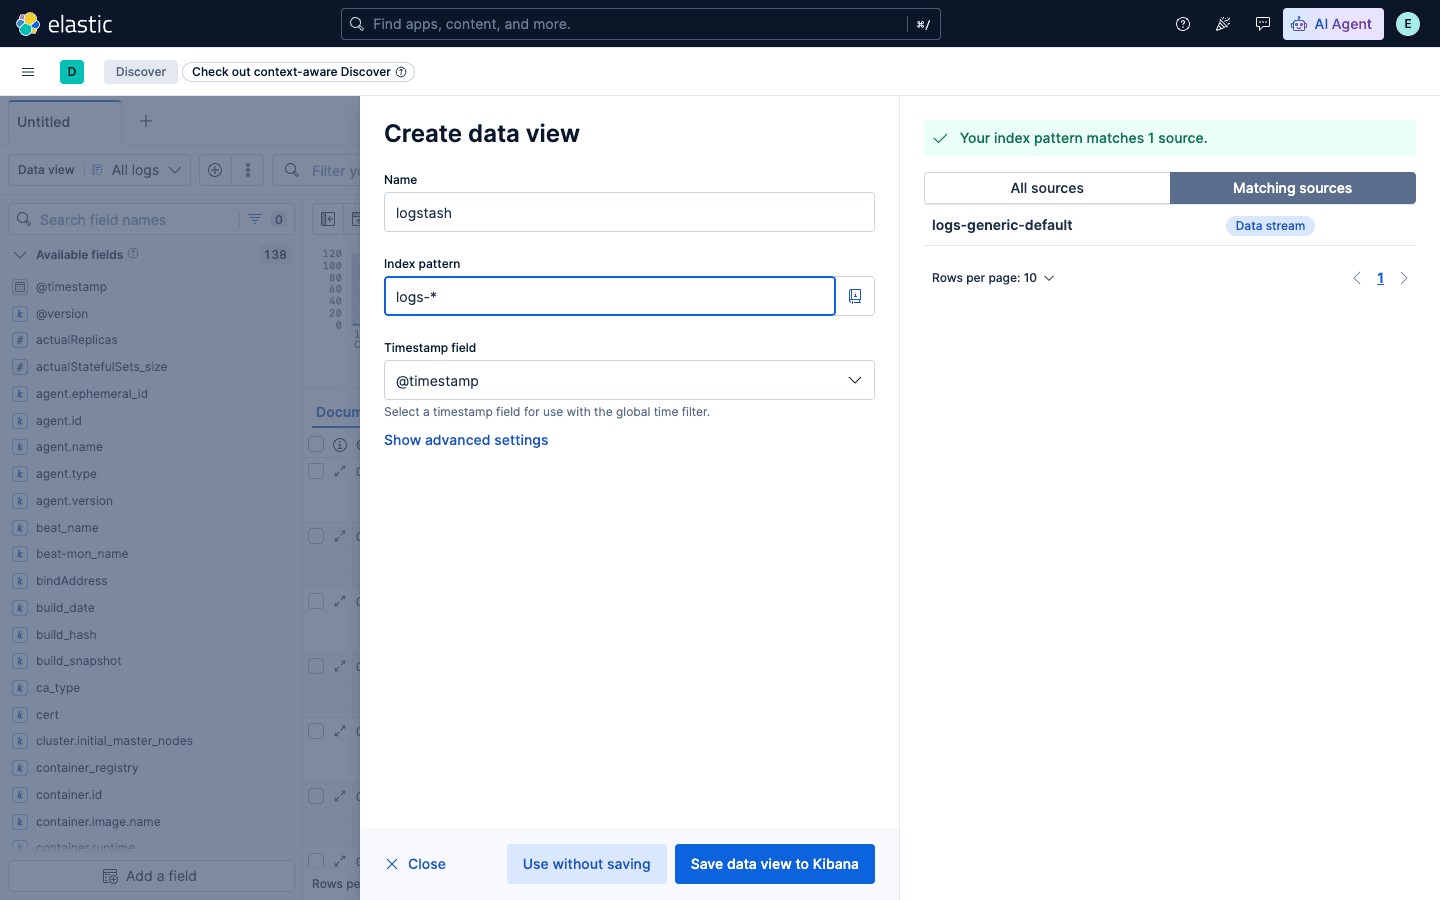
Create data view: in Discover, open the data view menu and select Create a data view. You can also find Data Views in the navigation menu or through the global search, then select Create data view. Fill in the form:
- Name: logstash
- Index pattern:
logs-* - Timestamp field: @timestamp
Why logs-* and not logstash-*? Starting with Logstash 8.0, the Elasticsearch output writes to a data stream by default. With the pipeline above, events land in the logs-generic-default data stream. Older Logstash versions wrote daily logstash-YYYY.MM.dd indices, which is where the logstash-* pattern comes from.
Create data view: logs-* matches the logs-generic-default data stream
You should now see logs from the deployed application. To show only the counter Pod, type kubernetes.pod.name : "counter" in the search bar.
If nothing shows up, check each hop from the source:
shell
1kubectl get pods -n elastic-stack2kubectl logs daemonset/quickstart-beat-filebeat -n elastic-stack3kubectl logs quickstart-ls-0 -n elastic-stackFilebeat logs show whether it reads files and connects to Logstash. Logstash logs show whether it can write to Elasticsearch.
Two things look alarming but are expected in this demo. Elasticsearch HEALTH turns yellow once logs arrive: the logs-generic-default data stream asks for one replica, and a single node has nowhere to put it. Filebeat also logs errors about the elasticsearch and kibana modules and duplicated input IDs. ECK adds Filebeat hints to its own Pods, and those inputs fail to start. Logs from your other Pods still flow.
Wrapping up and next steps
You've deployed the ELK Stack on Kubernetes with the ECK operator: Filebeat collects container logs, Logstash processes them, Elasticsearch stores them, and Kibana lets you search and visualize them.
Keep in mind that this is a learning and test setup. Before you put production logs into it, plan for:
- at least three Elasticsearch nodes and replica shards;
- vm.max_map_count set to 1048576 instead of node.store.allow_mmap: false;
- a storage class, volume size, and resources sized for your log volume;
- retention with index lifecycle management, and snapshots for backups;
- valid certificates for Kibana and SSL between Filebeat and Logstash.
Manage your logs: the counter Pod filtered with kubernetes.pod.name : "counter"
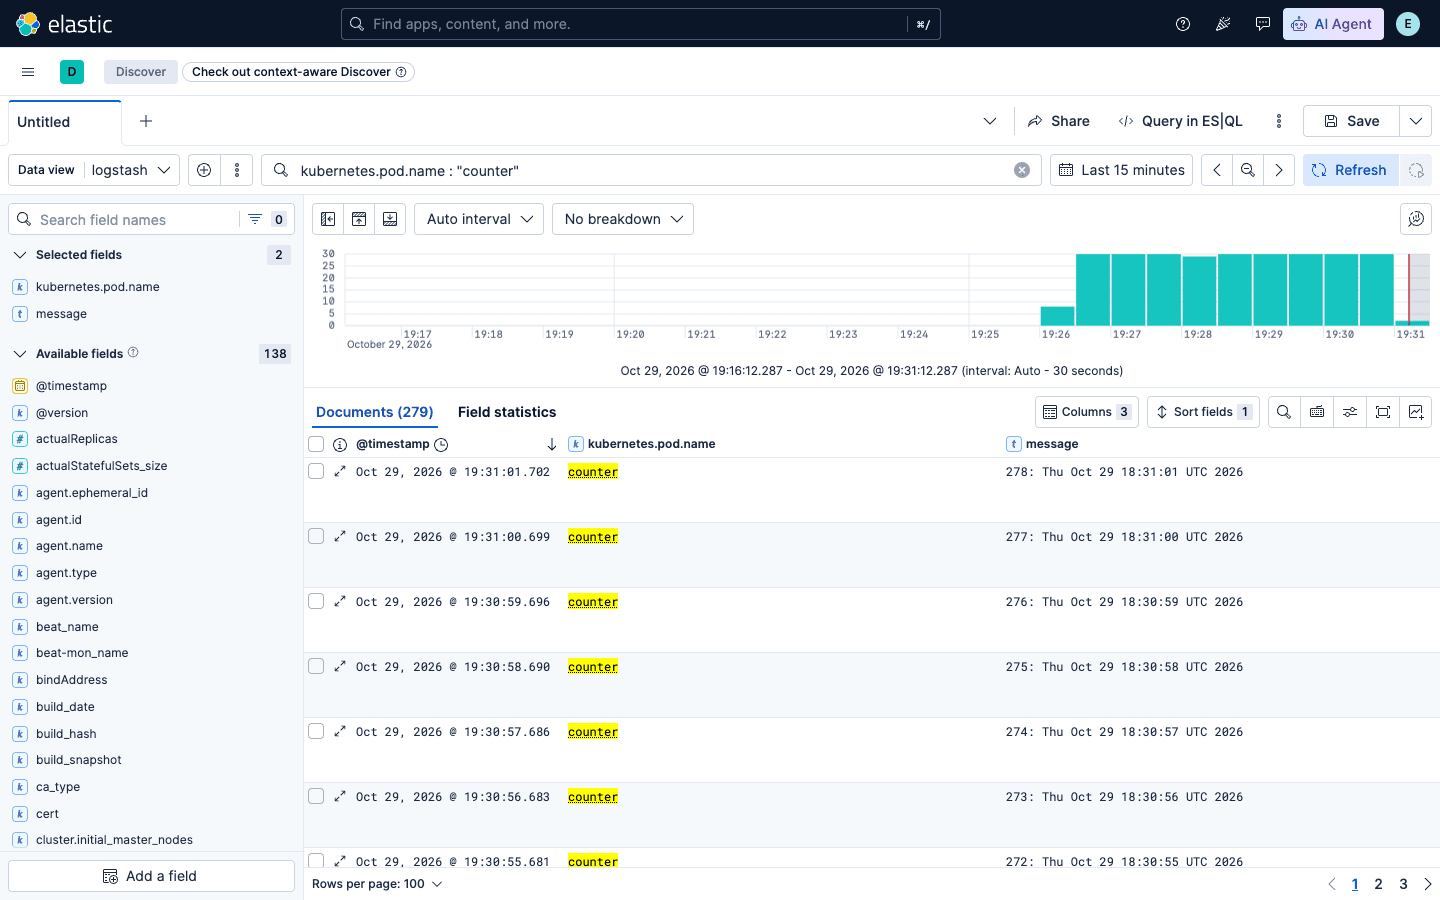
Now you can search and filter the logs of all your Pods in one place instead of running kubectl logs one Pod at a time.
Feel free to reach out if you have any questions or need help running logging and monitoring in production.