Overview
When users visit your site, a web server handles the request. But every web server has CPU and memory limits, so if too many requests arrive at once, it slows down or falls over. The fix is to run more servers and spread the traffic evenly between them. Before adding servers, make sure the ones you have are tuned: see what server optimization covers.
That is the load balancer's job. Requests go to the load balancer first, and it picks a backend server using a load-balancing algorithm. It also stops sending traffic to servers that fail, which is what makes high availability possible. The load balancer itself can become a single point of failure, so production setups run at least two of them (more on that below).
Short history of load balancers
In the 1990s, early internet startups hit a wall. They couldn't afford the most powerful machines of the day, only standard servers from PC manufacturers, and those couldn't handle their traffic alone. So some of those pioneers put a load balancer in front of several off-the-shelf servers and sent requests to each in turn, round-robin style. A group of servers working together like this is often called a server farm. It solved their scaling problem. Load balancing grew directly out of hardware limits that blocked business growth.
Types of traffic load balancers can handle
Depending on the design and purpose, load balancers work at one of two levels:
- Layer 4 (transport). The load balancer sees IP addresses, ports and protocols (TCP, UDP), but not the content. It's fast and works for any protocol: databases, MQTT, game servers, DNS, anything over TCP or UDP.
- Layer 7 (application). The load balancer understands HTTP. It can route by host name, URL path, header or cookie, terminate TLS, add headers like
X-Forwarded-For, and retry a failed request on another server.
Most products support several traffic types:
- HTTP. The load balancer receives the request, picks a backend using the rules you set, and forwards it. It usually adds headers so the backend knows the real client IP and protocol.
- HTTPS. With TLS termination, the load balancer decrypts the request and passes it to the backend (unencrypted or re-encrypted). With TLS passthrough, it forwards the encrypted stream as is and the backend decrypts it. Passthrough keeps the keys on your servers, but the load balancer can't see or route by HTTP content.
- HTTP/2, gRPC and WebSocket. Modern Layer 7 load balancers handle long-lived and multiplexed connections. Check that both sides (client to load balancer and load balancer to backend) support the protocol you need.
- TCP. Useful for services like LDAP, MySQL, PostgreSQL, Redis and RTMP.
- UDP. Standard today in NGINX and in the Layer 4 load balancers of every major cloud. It's used for DNS, Syslog, RADIUS, VoIP, game traffic and QUIC.
Load balancing algorithms
The algorithm decides which backend server gets each request or connection. Here are the common ones and how they work in real products:
- Round robin. Requests go to each server in turn. It's the default in NGINX, HAProxy and the AWS Application Load Balancer. With weights, a server with
weight=3gets three times the share of a server with weight 1. Good when servers are similar and requests cost about the same. - Least connections. The next request goes to the server with the fewest active connections (
least_connin NGINX,balance leastconnin HAProxy). It handles uneven request times better than round robin, and HAProxy recommends it for very long sessions such as LDAP and SQL. The AWS Application Load Balancer has a close relative, least outstanding requests. - Least response time. The server with the lowest average response time and fewest active connections wins. In NGINX this is
least_time: it has long been part of NGINX Plus and arrived in open source NGINX only in the 1.31 mainline branch, so the 1.30 stable release doesn't have it. HAProxy has no response-time method. - Hash. The server is chosen from a hash of a key: client IP, URL, header or cookie. The same key always lands on the same server while the pool doesn't change. NGINX has
ip_hash(it uses only the first three octets of an IPv4 address, so a whole /24 network goes to one server) and the more flexiblehash $remote_addr consistent. HAProxy hasbalance source,uri,hdrand others. Hashing gives stickiness without cookies, but a big office behind one NAT address will pin all its users to a single server. - Random with two choices. The load balancer picks two servers at random and sends the request to the less loaded one. It spreads load well when there are many servers or several load balancers that don't share state. NGINX has
random two least_conn, HAProxy hasbalance random(two draws by default). - Flow hash (cloud Layer 4). Network load balancers in the cloud don't round-robin. The AWS Network Load Balancer, for example, hashes the protocol, source and destination IP and port, and the TCP sequence number, then keeps the whole connection on one target.
Which algorithms you get depends on the product. Cloud load balancers usually offer two or three, open source proxies offer more, and hardware ADCs often add their own.
Special considerations for load balancers
Besides traffic types and algorithms, you need to plan for the following:
Health checks
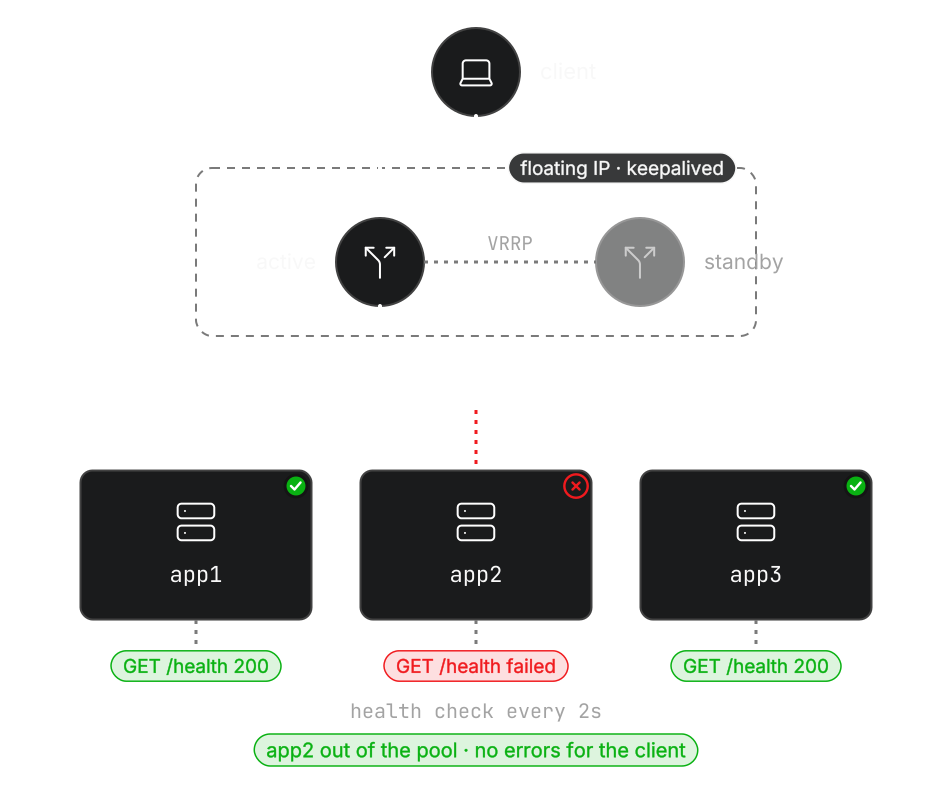
Backend servers fail, hang or start returning errors. Health checks make sure the load balancer stops sending them traffic. There are two kinds:
- Active checks. The load balancer sends its own probe (a TCP connect or an HTTP request to a path like
/health) every few seconds and marks the server down after several failures. HAProxy, the cloud load balancers and NGINX Plus do this. Open source NGINX doesn't: thehealth_checkdirective is NGINX Plus only. - Passive checks. The load balancer watches real requests. In open source NGINX,
max_failsandfail_timeouttake a server out after a number of failed attempts. The catch is that real users pay for discovering the failure: in our test, about one request in ten waited out the 2-second connect timeout before NGINX moved it to a healthy server.
A good health endpoint checks what the app needs to serve traffic (for example, that it can reach its database) and returns a non-200 status when it can't. A check that only tests the TCP port will keep sending traffic to an app that is up but returning 500s.
Redundancy and high availability
A single load balancer is a single point of failure, so you run at least two. On your own servers, the classic setup is an active-passive pair that shares a floating (virtual) IP address managed by keepalived over VRRP. If the active node dies, the standby takes over the IP within a few seconds, without waiting for DNS changes to propagate. Cloud load balancers handle this for you: they run across several availability zones and scale automatically.
Sticky sessions
If a user's session lives in a server's memory, every request from that user has to go to the same server. Load balancers usually solve this with a cookie: the first response sets a cookie that names the server, and later requests with that cookie go back to it. HAProxy does this with cookie ... insert, open source NGINX with sticky cookie (since version 1.29.6), and the AWS Application Load Balancer with the AWSALB cookie. If the pinned server goes down, the load balancer picks a new one and the user's in-memory session is lost. That's why the long-term fix is to keep sessions in a shared store like Redis or a database and drop stickiness.
Try it: NGINX and HAProxy with health checks in Docker
The fastest way to understand load balancing is to watch it. This setup runs three small backend servers and two load balancers in front of them: open source NGINX on port 8081 and HAProxy on port 8082. It was tested with Docker Engine 29, NGINX 1.30 and HAProxy 3.4.
Create the backends
Each backend is a tiny NGINX server that replies with its host name and has a /health endpoint. Save this as backend.conf:
nginx
1server {2 listen 8080;3
4 location /health {5 return 200 "ok\n";6 }7
8 location / {9 return 200 "$hostname\n";10 }11}Configure NGINX
Save this as nginx-lb.conf:
nginx
1upstream app {2 zone app 64k;3 least_conn;4 server app1:8080 max_fails=3 fail_timeout=10s;5 server app2:8080 max_fails=3 fail_timeout=10s;6 server app3:8080 max_fails=3 fail_timeout=10s;7 keepalive 16;8}9
10server {11 listen 80;12
13 location / {14 proxy_pass http://app;15 proxy_http_version 1.1;16 proxy_set_header Connection "";17 proxy_set_header Host $host;18 proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;19 proxy_connect_timeout 2s;20 proxy_next_upstream error timeout http_500 http_502 http_503;21 }22}A few lines matter more than they look:
zone app 64kshares the balancing state between NGINX worker processes. Without it, each worker balances on its own. In our test, nine requests right after a restart all went toapp1, because each landed on a different worker and every worker started from the first server. With the zone, they split 3/3/3.max_fails=3 fail_timeout=10sis the passive health check: after three failures within 10 seconds, the server is skipped for 10 seconds.proxy_next_upstreamlists what counts as a failure and lets NGINX retry the request on the next server. By default it's onlyerror timeout, so a backend that returns 500 keeps getting traffic. In our test, one in three users got a 500 until we addedhttp_500.- To pin users to one server, add
sticky cookie srv_id expires=1h;afterleast_conn. The order matters: placed before the balancing method, NGINX warns that the method was redefined and stickiness doesn't work.
Configure HAProxy
Save this as haproxy.cfg:
shell
1defaults2 mode http3 timeout connect 2s4 timeout client 30s5 timeout server 30s6 retries 27 option redispatch8
9frontend web10 bind :8011 default_backend app12
13backend app14 balance roundrobin15 option httpchk16 http-check send meth GET uri /health17 http-check expect status 20018 cookie SRV insert indirect nocache19 default-server inter 2s fall 3 rise 220 server app1 app1:8080 check cookie app121 server app2 app2:8080 check cookie app222 server app3 app3:8080 check cookie app323
24frontend stats25 bind :840426 stats enable27 stats uri /stats28 stats refresh 5sHAProxy checks /health on every server every 2 seconds (inter 2s). A server is marked down after 3 failed checks (fall 3) and back up after 2 good ones (rise 2). option redispatch with retries 2 sends a request to another server if the chosen one doesn't answer. The cookie line adds sticky sessions, and the stats page shows the state of each server.
Start the stack
Save this as compose.yaml in the same folder:
yaml
1services:2 app1: &app3 image: nginx:1.30-alpine4 hostname: app15 volumes:6 - ./backend.conf:/etc/nginx/conf.d/default.conf:ro7 app2:8 <<: *app9 hostname: app210 app3:11 <<: *app12 hostname: app313
14 nginx-lb:15 image: nginx:1.30-alpine16 volumes:17 - ./nginx-lb.conf:/etc/nginx/conf.d/default.conf:ro18 ports:19 - "8081:80"20 depends_on: [app1, app2, app3]21
22 haproxy-lb:23 image: haproxy:3.4-alpine24 volumes:25 - ./haproxy.cfg:/usr/local/etc/haproxy/haproxy.cfg:ro26 ports:27 - "8082:80"28 - "8404:8404"29 depends_on: [app1, app2, app3]Start it and check both configs:
shell
1docker compose up -d2docker compose exec nginx-lb nginx -t3docker compose exec haproxy-lb haproxy -c -f /usr/local/etc/haproxy/haproxy.cfgCheck the traffic distribution
Send 300 requests to each load balancer and count which server answered:
shell
1for i in $(seq 300); do curl -s localhost:8081; done | sort | uniq -c2for i in $(seq 300); do curl -s localhost:8082; done | sort | uniq -cBoth split the traffic evenly:
shell
1 100 app12 100 app23 100 app3To see stickiness in HAProxy, keep the cookie between requests. All requests now go to one server:
shell
1rm -f jar; for i in $(seq 50); do curl -s -b jar -c jar localhost:8082; done | sort | uniq -cshell
1 50 app1Simulate a failure
Stop one backend and send traffic again:
shell
1docker compose stop app22for i in $(seq 30); do curl -s -o /dev/null -w '%{http_code} %{time_total}\n' localhost:8081; doneEvery request still returns 200, but a few take about 2 seconds. That's NGINX hitting the dead server, waiting for the connect timeout and retrying on a healthy one. After that, the traffic is split between app1 and app3 only. HAProxy logs the failure from its own checks:
shell
1docker compose logs haproxy-lb | grep DOWNshell
1Server app/app2 is DOWN, reason: Layer4 timeout, check duration: 2007ms. 2 active and 0 backup servers left.The stats page at http://localhost:8404/stats shows app2 in red. Start it again with docker compose start app2: HAProxy marks it UP after two good checks, NGINX after fail_timeout runs out, and the traffic is back to an even split. When you're done, run docker compose down.
This is the main practical difference between the two tools in open source form. HAProxy finds a dead or broken server on its own, before users do. Open source NGINX learns about it from failed user requests, so keep timeouts short and list the error codes in proxy_next_upstream.
Hardware and software load balancers
There are hardware, software and cloud load balancers. Cloud load balancers are software too, but they are a separate category because the provider builds and runs them for you.
Hardware load balancers
Organizations buy hardware load balancers for raw throughput and predictable performance. They use specialized chips for TLS and packet processing, sit in your own data center, and are managed by your own team. The downsides: they cost more up front, need specialist skills, and scaling means buying and racking another box. Most vendors now sell the same software as virtual appliances and cloud images, so the line between hardware and software is thin.
Current vendors of hardware load balancers and ADCs:
- F5. The best-known ADC vendor. Its BIG-IP platform covers local and global load balancing, TLS offload, WAF and access control, and runs on F5 hardware, as virtual editions and in public clouds.
- NetScaler. Formerly Citrix ADC. NetScaler runs the same ADC software on hardware appliances, virtual machines, bare metal and containers.
- Progress Kemp. Kemp is now part of Progress. Its LoadMaster line comes as hardware appliances, virtual appliances and cloud images, and is known for being simpler and cheaper than the big two.
- A10 Networks. Thunder ADC offers load balancing, TLS offload and DDoS protection on hardware, virtual and container form factors.
- Radware. Its ADC line is Alteon, available as hardware and virtual appliances, with built-in WAF and bot protection options.
- Fortinet. FortiADC comes as hardware models with TLS offload and as virtual machines, and fits well if you already run FortiGate firewalls.
- Barracuda. Barracuda Load Balancer ADC is available as hardware, virtual and cloud instances.
- SKUDONET. Formerly Zevenet. SKUDONET is a software-based load balancer, sold as an open source community edition and an enterprise edition, including on hardware appliances.
Cisco used to sell dedicated load balancers (the ACE line), but stopped selling them in 2012.
Software load balancers
Software load balancers run on ordinary servers, virtual machines and containers. They are cheaper, easier to automate and scale out by adding instances, which is why most teams start here. You can run them on cloud instances too, for example NGINX or HAProxy on EC2 in front of your app servers. They still need people who know how to tune, monitor and patch them.
The most widely used options:
- NGINX. Open source NGINX balances HTTP, TCP and UDP with round robin, least connections, hash, IP hash and random. Since version 1.29.6 it also has cookie-based sticky sessions. Active health checks, a live API and dashboard are still part of the commercial NGINX Plus from F5.
- HAProxy. HAProxy is a free, open source load balancer used by companies like GitHub, Reddit, Stack Overflow and Airbnb. It has active health checks, many algorithms, detailed stats, TLS offload and rate limiting in the free version. The current long-term support branch is 3.4. HAProxy Enterprise adds a WAF, bot management and support.
- Envoy. Envoy is a CNCF proxy built for microservices. It's the data plane behind Istio and many API gateways, with strong support for HTTP/2, gRPC, retries and observability.
- Traefik. Traefik discovers services from Docker, Kubernetes and other providers and configures itself, which makes it popular for container setups.
- Caddy. Caddy is a web server with automatic HTTPS and a simple reverse proxy with load balancing and health checks. A good fit for small setups.
- Apache HTTP Server. Its proxy balancer module (
mod_proxy_balancer) adds load balancing to Apache. It works fine if you already run Apache, but new setups usually choose NGINX, HAProxy or Envoy. - Progress Kemp free LoadMaster. Kemp offers a free LoadMaster virtual appliance with a WAF. It's capped at 20 Mbps of throughput, so it suits labs and small sites.
On Linux, IPVS (Linux Virtual Server) with keepalived is still a common choice for fast Layer 4 balancing. In Kubernetes, Services handle internal balancing, while Ingress controllers and the newer Gateway API bring traffic in from outside, usually with NGINX, HAProxy, Envoy or Traefik underneath.
Cloud load balancers
Moving to the cloud didn't remove the need for load balancers. Early cloud adopters ran software load balancers on their own instances. Today every major provider offers managed load balancers that scale and fail over on their own. Anyone building in the cloud should know what's available.
AWS Elastic Load Balancing
Elastic Load Balancing (ELB) spreads traffic across EC2 instances, containers, IP addresses and Lambda functions in one or more availability zones, and only sends it to healthy targets. AWS currently offers four types:
- Application Load Balancer (ALB). Layer 7, for HTTP, HTTPS, HTTP/2, gRPC and WebSocket. It routes by host, path, header and query string, terminates TLS, and works with AWS WAF. Algorithms: round robin (default), least outstanding requests and weighted random.
- Network Load Balancer (NLB). Layer 4, for TCP, UDP, TLS and QUIC with very low latency and static IP addresses per zone. It uses a flow hash, so each connection stays on one target.
- Gateway Load Balancer (GWLB). Layer 3, for inserting third-party virtual appliances such as firewalls and intrusion detection systems into the traffic path. It talks to the appliances over the GENEVE protocol.
- Classic Load Balancer. The previous generation. AWS recommends migrating to a current load balancer type.
With Auto Scaling, new instances register with the load balancer automatically and terminated ones are removed. With IP targets, ALB and NLB can also send traffic to on-premises servers over VPN or Direct Connect.
Azure load balancing
Azure splits load balancing across several services:
- Azure Load Balancer. Layer 4 (TCP and UDP), regional or cross-region, zone-redundant, with a 99.99% SLA. It comes in the Standard SKU and the Gateway SKU (for chaining third-party network virtual appliances). The Basic SKU was retired on September 30, 2025, and Microsoft asks remaining users to upgrade to Standard. Standard is closed to inbound traffic until you allow it with a network security group.
- Application Gateway. Regional Layer 7 load balancer with TLS termination, path-based routing and an optional WAF. There's also Application Gateway for Containers for Kubernetes workloads.
- Azure Front Door. Global Layer 7 entry point with CDN caching, TLS offload, WAF and fast failover between regions.
- Traffic Manager. DNS-based global load balancing. It fails over more slowly than Front Door because clients cache DNS answers.
Microsoft's load balancing options guide has a decision tree for choosing between them, and the SKU comparison covers the retired Basic SKU.
Google Cloud Load Balancing
Google Cloud Load Balancing has three product families, each in external and internal, global and regional variants:
- Application Load Balancer. Layer 7 proxy for HTTP and HTTPS, with URL maps, managed TLS certificates, Cloud CDN and Cloud Armor (WAF and DDoS protection).
- Proxy Network Load Balancer. Layer 4 proxy for TCP, with optional TLS offload in the global external version.
- Passthrough Network Load Balancer. Layer 4 without a proxy, so backends see the original client IP. It supports TCP, UDP and other IP protocols such as ESP, GRE and ICMP.
The global external load balancers use a single anycast IP address and send users to the closest healthy region. The overview page helps you pick the right one. Pricing depends on forwarding rules and the amount of data processed.
DigitalOcean Load Balancers
DigitalOcean is popular with startups and small teams. Its load balancers are fully managed and highly available, and send traffic to Droplets (DigitalOcean's virtual machines) and Kubernetes nodes. There are two types:
- Regional load balancers work within one data center region and support HTTP, HTTPS, HTTP/2, HTTP/3, TCP and UDP, with TLS termination or passthrough and cookie-based sticky sessions. Regional network load balancers handle Layer 4 TCP and UDP traffic, and you can make a load balancer internal so it's reachable only from your VPC.
- Global load balancers spread traffic across regions and add CDN caching.
DigitalOcean doesn't let you choose an algorithm: the load balancer assigns new connections as evenly as it can.
Cloudflare Load Balancing
Cloudflare Load Balancing works at Cloudflare's edge in front of your servers, wherever they run. It checks your endpoints from several locations, fails over when one stops answering, and can route by latency, the visitor's region or their location, so European users go to European servers and US users to US servers. It's a paid add-on to a Cloudflare plan.
Imperva
Imperva, now part of Thales, includes load balancing and failover in its cloud application security service. It can balance between servers in one data center and between data centers, alongside its WAF and DDoS protection.
Note: Even with a managed cloud load balancer available, you can still run your own software load balancer on cloud instances, for example to keep the same NGINX or HAProxy setup across clouds.
Considerations for choosing load balancers
There are many options. When you choose one, think about the following:
- Business requirements. It's tempting to take the path of least resistance and use your cloud provider's load balancer. That's often the right call. But if you may move to a hybrid model (cloud plus on-premises) or use several clouds, a portable software load balancer may save you a migration later. Choose with your future plans in mind.
- Workload estimates. Estimate how your traffic will grow. Some services become expensive at high volume (cloud load balancers bill for data processed), and some setups won't scale far enough. Plan for future load, not just today's.
- High availability. If your application must stay up, you need redundant load balancers, health checks that test the real app, and capacity to lose a node or a zone. If it doesn't, don't pay for premium appliances you don't need. Match the solution to your service level targets.
- Security. Growing traffic also makes you a bigger target. Look for TLS offload with modern ciphers, a WAF, rate limiting and DDoS protection, either in the load balancer itself or in front of it.
- Return on investment (ROI). Even a free load balancer takes time to learn, configure and run. Add up hardware, software or subscription costs and the time your team will spend on it, and compare the total cost of ownership (TCO). If your team doesn't have that time, our cloud engineering team can design and run the load balancing layer for you.