A monitoring system has one job: tell the right person that users are in trouble, early enough to fix it, and give them what they need to find out why.
Everything else, the graphs, the exporters, the log pipelines, exists to serve that job. When monitoring is organized around the tools instead of the job, you get the classic result: hundreds of alerts, dashboards nobody opens, and outages that customers report before the pager does.
We've worked with 100+ companies, from a single server to multi-cluster Kubernetes platforms. This article is how we organize monitoring today: the principles first, then the stack, then a small lab you can run on your laptop to see every piece working.
What a monitoring system has to answer
The Google SRE book puts it in two questions: what's broken, and why? The "what" is the symptom users feel. The "why" is the cause somewhere in your system.
To answer both, monitoring has to cover several layers:
- Users and business. Can people log in, pay, get a response in time? How many orders per minute, how long since the last one?
- Application. Request rate, errors and latency per service, queue depth, background jobs.
- Platform. Kubernetes nodes and pods, autoscaling, managed databases, load balancers, cloud services.
- Infrastructure. CPU, memory, disk, network, certificates.
Most teams start at the bottom and never get to the top. It should be the other way round: the top layers tell you that something is wrong, the bottom layers help you find where.
Why server-only monitoring stopped working
Watching CPU, memory, disk and network used to be enough when a project was one PHP app on one server. Today it tells you very little. A server can look perfectly healthy while checkout fails because a third-party API times out.
Modern systems are also dynamic. With containers and Kubernetes HPA, pods come and go every few minutes, and nobody maintains a list of hosts by hand. The monitoring system has to discover targets on its own and group them by labels like service, namespace and environment.
That's the main reason Prometheus-style monitoring took over in cloud-native setups. Host-centric tools still have their place. Zabbix can discover hosts and items automatically with low-level discovery, and it's a solid choice for networks, hardware and classic VMs. But it's built around hosts and templates, which fits short-lived pods worse than service discovery and labels.
Metrics, logs and traces
Observability is usually split into three signals. You need all three, but not for the same job.
Metrics
Metrics are numbers over time: requests per second, error ratio, p95 latency, free disk space. They're cheap to store and fast to query, so they power alerts and dashboards. Prometheus is the de facto standard here, with compatible backends like VictoriaMetrics or Grafana Mimir when you need long retention or many clusters.
Logs
Logs explain what happened in a specific request or process. They're the first place you look once an alert has told you where. Grafana Loki indexes only labels, not full text, which keeps it cheap. If you need full-text search and analytics over logs, the ELK stack is still the stronger tool, see our guide on deploying ELK on Kubernetes.
Traces
Traces follow one request across services and show where the time went. They answer "which of the twelve services made this slow". OpenTelemetry is now the standard way to instrument code and collect traces, metrics and logs. It replaced OpenTracing, which is archived. Traces usually go to Grafana Tempo or Jaeger if you self-host, or to a SaaS APM like New Relic or Datadog.
Start with SLIs and SLOs
Before you write a single alert, decide what "working" means for users. That's what SLIs and SLOs are for.
- SLI (service level indicator): a measurement of user experience. For example, the share of HTTP requests that return a non-5xx response in under 500 ms.
- SLO (service level objective): the target for that SLI over a period. For example, 99.9% of requests are good over 30 days.
- Error budget: what the SLO allows to fail. 99.9% over 30 days is about 43 minutes of full downtime, or the same amount of errors spread over the month.
SLOs change the conversation. Instead of "CPU is at 90%, is that bad?" you ask "are we spending the error budget faster than we can afford?" That question has an answer, and it's the one the business cares about.
The SRE Workbook recommends alerting on the burn rate of the error budget with two windows. For a 99.9% SLO the starting point is:
- Page if the budget burns 14.4 times faster than allowed over the last hour and the last 5 minutes (2% of the monthly budget gone in an hour).
- Page if it burns 6 times faster over 6 hours and the last 30 minutes (5% gone).
- Ticket if it burns at 1x over 3 days and the last 6 hours (10% gone).
The short window makes the alert stop firing soon after the problem is fixed. You'll find both rules in the lab below.
Alert on symptoms, not causes
A page should mean "users are affected right now, or will be very soon". That's a symptom: the site doesn't respond, the error ratio is up, checkout latency doubled, the error budget is burning.
Causes are different. High CPU, a restarted pod, a replica lagging behind: each of these may or may not hurt users. If you page on them, people learn to ignore the pager. The Prometheus alerting guide says the same: keep alerting simple, alert on symptoms, and have good dashboards to find causes.
So causes go to one of two places:
- A ticket, if someone has to act during working hours. A disk that will be full in 24 hours, a TLS certificate that expires in two weeks, a scrape target that disappeared.
- A dashboard, if it only matters while you investigate a symptom.
The one exception is a cause that predictably becomes an outage too fast for a ticket, like a disk filling up in the next hour. That can page, but it should be rare.
Organize alerts so on-call doesn't burn out
Alert fatigue is how good monitoring dies. Every false or useless page teaches the on-call engineer that pages can wait. These rules keep the pager quiet enough to trust.
Use two severities, not five
We use page and ticket. A page wakes someone up. A ticket goes to a channel or a queue and gets handled during the day. "Warning", "minor" and "info" levels that nobody acts on are just noise with extra steps.
Every page needs a runbook
Each alert carries a summary that says what users feel and a runbook_url that says what to check first. The engineer who gets paged at 3 AM may have never touched this service. The runbook doesn't have to be long: what the alert means, the first three commands, who owns the service.
Group, deduplicate and inhibit
When a service goes down, ten alerts can fire at once. Alertmanager groups them into one notification by labels like alertname and service, waits a few seconds to collect related alerts, and repeats only after a set interval.
Inhibition rules mute lower-severity alerts while a related page is active. If the service is already down and someone is paged, there's no point in also opening a ticket that its error budget is shrinking. In the lab below you'll see exactly that: the ticket is held back while the page is active and sent only after the service recovers.
Review every page
After each on-call shift, go through the pages. For every one, ask: was it real, was it actionable, did it come early enough? Delete or downgrade alerts that fail the test. If an outage happened without a page, add the missing check. Google's chapter on being on-call is a good reference for what a sustainable rotation looks like.
Monitor the monitoring
If Prometheus or Alertmanager dies, all your alerts die with it, silently. Two checks cover this:
- A Watchdog alert that always fires and goes to an external heartbeat service such as Healthchecks. If the heartbeat stops arriving, that service pages you.
- An external probe from outside your infrastructure that checks your main endpoints. If the whole region or data center goes down, it still sees it.
Dashboards that answer questions
A good dashboard answers one question fast. A bad one shows everything and explains nothing. We build them in three levels:
- Overview. One screen per product: SLOs, error budget, endpoint status, firing alerts. This is what you open when you get paged.
- Service. For each service, rate, errors and duration (the RED method), plus its dependencies.
- Resource. For hosts, nodes and databases, utilization, saturation and errors (the USE method).
A few habits make them useful under pressure:
- Put symptoms at the top and causes below, in the order you'd check them.
- Add deployment markers with annotations. Many incidents start right after a release, and a marker on the graph answers "did we just deploy?" before anyone asks.
- Keep dashboards and data sources in Git and load them with provisioning, so a broken edit can be reverted like any other change.
That's how we restructured monitoring for a healthcare AI startup on Kubernetes: separate infrastructure, application and SLO layers, fewer alerts tied to SLOs, and deployment markers on the dashboards.
Business metrics are monitoring too
The business needs its own graphs: orders per minute, sign-ups, payments, time since the last order. They're also some of the best symptom alerts you can have.
If an online store usually gets an order every few minutes and suddenly gets none for half an hour during peak time, something is broken, even if every technical check is green. A payment provider changed its API, a form lost a field, a feature flag went wrong. Expose these numbers as metrics from the application or the database and alert on them like any other SLI.
To do that, you need to know how the business works: which flows bring money, what analysts track, and what "normal" looks like on a Monday morning versus a Sunday night. That's a conversation with the product team, not a config file.
The stack we use
There's no single right stack, but this is what we deploy most often for cloud and Kubernetes projects.
Prometheus and exporters
Prometheus scrapes metrics and evaluates alert rules. Exporters turn systems into metrics: node_exporter for Linux hosts, blackbox_exporter for HTTP, TCP, DNS and ICMP probes from the outside, plus exporters for databases, queues and web servers. In Kubernetes we run it with the Prometheus Operator, so each team adds monitoring for its service next to the deployment.
Alertmanager and on-call
Alertmanager receives alerts from Prometheus and decides who gets them and how: grouping, routing by severity and team, silences during maintenance, inhibition. Pages go to an on-call tool like PagerDuty with schedules and escalation. Tickets go to Slack or the team's issue tracker.
Grafana
Grafana is where people look. It reads from Prometheus, Loki, Tempo, CloudWatch and most databases, so one dashboard can show a symptom, the related logs and the traces side by side.
Loki and the OpenTelemetry Collector
Loki stores logs, and the OpenTelemetry Collector ships them. Loki accepts OpenTelemetry data natively over OTLP, so the same collector can later carry traces to Tempo and metrics to Prometheus. One agent per node instead of three.
Cloud monitoring
Managed services like RDS, ALB, SQS or Lambda report to Amazon CloudWatch. You can read them in Grafana with the CloudWatch data source, or pull them into Prometheus with YACE so alerts live in one place. Other clouds have the same pattern with their own monitoring services.
SaaS and classic tools
SaaS platforms like Datadog and New Relic give you all of this with less work and a bigger bill. For a small team without someone to run the stack, that can be the right call. Nagios and Zabbix still make sense for on-prem networks and hardware. The principles in this article apply to any of them.
Try it: a monitoring stack in Docker Compose
Reading about alert routing is one thing. Watching an alert fire, get grouped, page someone and hold back a ticket is another. This lab runs the whole chain on one machine with Docker Compose:
- Prometheus with alert rules;
node_exporterfor host metrics;blackbox_exporterprobing two HTTP endpoints;- Alertmanager with page and ticket routes;
- Grafana with provisioned data sources;
- Loki with the OpenTelemetry Collector shipping container logs;
- a demo NGINX service called
shopthat you'll break on purpose.
Tested on Docker Desktop with Prometheus 3.15, Alertmanager 0.34, node_exporter 1.12, blackbox_exporter 0.29, Grafana 13.3, Loki 3.7 and OpenTelemetry Collector 0.164.
Project layout
Create this structure:
shell
1monitoring-lab/2├── docker-compose.yml3├── prometheus/4│ ├── prometheus.yml5│ ├── rules/alerts.yml6│ └── tests/alerts_test.yml7├── blackbox/blackbox.yml8├── alertmanager/9│ ├── alertmanager.yml10│ └── secrets/11├── otel/config.yaml12└── grafana/provisioning/datasources/datasources.ymlKeep the rule tests outside rules/. Prometheus loads every file that matches the rule_files glob, and a test file there breaks rule loading.
The Compose file
Every service pins its version, and only Prometheus, Alertmanager and Grafana publish ports, bound to 127.0.0.1:
yaml
1services:2 prometheus:3 image: prom/prometheus:v3.15.14 command:5 - --config.file=/etc/prometheus/prometheus.yml6 - --storage.tsdb.retention.time=15d7 - --web.enable-lifecycle8 volumes:9 - ./prometheus:/etc/prometheus:ro10 - prometheus-data:/prometheus11 ports:12 - "127.0.0.1:9090:9090"13
14 alertmanager:15 image: prom/alertmanager:v0.34.216 command:17 - --config.file=/etc/alertmanager/alertmanager.yml18 volumes:19 - ./alertmanager:/etc/alertmanager:ro20 ports:21 - "127.0.0.1:9093:9093"22
23 node-exporter:24 image: prom/node-exporter:v1.12.125 command:26 - --path.rootfs=/host27 pid: host28 volumes:29 - /:/host:ro,rslave30
31 blackbox:32 image: prom/blackbox-exporter:v0.29.133 command:34 - --config.file=/etc/blackbox/blackbox.yml35 volumes:36 - ./blackbox:/etc/blackbox:ro37
38 loki:39 image: grafana/loki:3.7.940 command:41 - -config.file=/etc/loki/local-config.yaml42
43 otel-collector:44 image: otel/opentelemetry-collector-contrib:0.164.045 command:46 - --config=/etc/otelcol/config.yaml47 user: "0"48 volumes:49 - ./otel/config.yaml:/etc/otelcol/config.yaml:ro50 - /var/lib/docker/containers:/var/lib/docker/containers:ro51
52 shop:53 image: nginx:1.30.6-alpine54
55 grafana:56 image: grafana/grafana:13.3.057 environment:58 GF_SECURITY_ADMIN_PASSWORD: change-me59 volumes:60 - ./grafana/provisioning:/etc/grafana/provisioning:ro61 - ./grafana/dashboards:/var/lib/grafana/dashboards:ro62 - grafana-data:/var/lib/grafana63 ports:64 - "127.0.0.1:3000:3000"65
66volumes:67 prometheus-data:68 grafana-data:On Docker Desktop for Mac or Windows, remove ,rslave from the node-exporter volume. Docker Desktop's VM doesn't mount its root as shared, and the container won't start with it. node_exporter will then report the metrics of the Docker Desktop VM, which is fine for a lab.
Prometheus configuration
Prometheus scrapes itself, Alertmanager and node_exporter directly. The blackbox job is different: Prometheus asks blackbox_exporter to probe each URL, and the relabeling turns the URL into a target parameter and an instance label:
yaml
1global:2 scrape_interval: 30s3 evaluation_interval: 30s4 external_labels:5 env: lab6
7rule_files:8 - /etc/prometheus/rules/*.yml9
10alerting:11 alertmanagers:12 - static_configs:13 - targets: ["alertmanager:9093"]14
15scrape_configs:16 - job_name: prometheus17 static_configs:18 - targets: ["localhost:9090"]19
20 - job_name: alertmanager21 static_configs:22 - targets: ["alertmanager:9093"]23
24 - job_name: node25 static_configs:26 - targets: ["node-exporter:9100"]27
28 - job_name: blackbox-http29 metrics_path: /probe30 params:31 module: [http_2xx]32 static_configs:33 - targets: ["http://grafana:3000/api/health"]34 labels:35 service: grafana36 - targets: ["http://shop/"]37 labels:38 service: shop39 relabel_configs:40 - source_labels: [__address__]41 target_label: __param_target42 - source_labels: [__param_target]43 target_label: instance44 - target_label: __address__45 replacement: blackbox:9115The service label is what Alertmanager groups and inhibits by later. Put it on every target from day one.
Blackbox module
One module for HTTP checks. A probe succeeds on any 2xx response within the timeout:
yaml
1modules:2 http_2xx:3 prober: http4 timeout: 10s5 http:6 preferred_ip_protocol: ip47 follow_redirects: trueAlert rules
Three groups: symptoms that page, causes that open tickets, and the Watchdog:
yaml
1groups:2 - name: symptoms3 rules:4 - alert: EndpointDown5 expr: probe_success == 06 for: 2m7 labels:8 severity: page9 annotations:10 summary: "{{ $labels.instance }} is not responding"11 description: "Blackbox probe has failed for 2 minutes."12 runbook_url: https://wiki.example.com/runbooks/endpoint-down13
14 - alert: AvailabilitySLOBurnRateFast15 expr: |16 (17 (1 - avg_over_time(probe_success[1h])) > (14.4 * 0.001)18 and19 (1 - avg_over_time(probe_success[5m])) > (14.4 * 0.001)20 )21 or22 (23 (1 - avg_over_time(probe_success[6h])) > (6 * 0.001)24 and25 (1 - avg_over_time(probe_success[30m])) > (6 * 0.001)26 )27 labels:28 severity: page29 annotations:30 summary: "{{ $labels.service }} is burning its 99.9% error budget too fast"31 runbook_url: https://wiki.example.com/runbooks/slo-burn32
33 - alert: AvailabilitySLOBurnRateSlow34 expr: |35 (1 - avg_over_time(probe_success[3d])) > 0.00136 and37 (1 - avg_over_time(probe_success[6h])) > 0.00138 labels:39 severity: ticket40 annotations:41 summary: "{{ $labels.service }} has used 10% of its monthly error budget in 3 days"42 runbook_url: https://wiki.example.com/runbooks/slo-burn43
44 - name: causes45 rules:46 - alert: DiskWillFillIn24h47 expr: |48 predict_linear(node_filesystem_avail_bytes{fstype!~"tmpfs|overlay"}[6h], 24 * 3600) < 049 and50 node_filesystem_avail_bytes{fstype!~"tmpfs|overlay"} / node_filesystem_size_bytes < 0.251 for: 30m52 labels:53 severity: ticket54 annotations:55 summary: "Disk {{ $labels.mountpoint }} on {{ $labels.instance }} will be full within 24h"56
57 - alert: CertificateExpiresSoon58 expr: (probe_ssl_earliest_cert_expiry - time()) / 86400 < 1459 for: 1h60 labels:61 severity: ticket62 annotations:63 summary: "TLS certificate for {{ $labels.instance }} expires in {{ $value | humanize }} days"64
65 - alert: ScrapeTargetDown66 expr: up == 067 for: 5m68 labels:69 severity: ticket70 annotations:71 summary: "Prometheus cannot scrape {{ $labels.job }} on {{ $labels.instance }}"72
73 - name: meta74 rules:75 - alert: Watchdog76 expr: vector(1)77 labels:78 severity: heartbeat79 annotations:80 summary: "Always firing. If the heartbeat receiver stops getting this, the alerting pipeline is broken."A few details matter here:
EndpointDownwaits 2 minutes (for: 2m) so a single failed probe doesn't wake anyone up.- The burn-rate rules follow the SRE Workbook table for a 99.9% SLO. Each uses a long and a short window joined with
and. DiskWillFillIn24hneeds both a trend and less than 20% free space, otherwise a big but nearly empty disk with some growth would trigger it.Watchdogusesvector(1), so it fires as long as Prometheus evaluates rules.
Test the rules
promtool can run unit tests against rules with synthetic time series. This test checks that EndpointDown doesn't fire a minute and a half into an outage and does fire after the 2-minute for:
yaml
1rule_files:2 - ../rules/alerts.yml3
4evaluation_interval: 30s5
6tests:7 - interval: 30s8 input_series:9 - series: 'probe_success{instance="http://shop/", service="shop"}'10 values: '1x10 0x10'11 alert_rule_test:12 - eval_time: 7m13 alertname: EndpointDown14 exp_alerts: []15 - eval_time: 8m16 alertname: EndpointDown17 exp_alerts:18 - exp_labels:19 severity: page20 instance: http://shop/21 service: shop22 exp_annotations:23 summary: "http://shop/ is not responding"24 description: "Blackbox probe has failed for 2 minutes."25 runbook_url: https://wiki.example.com/runbooks/endpoint-downThe series 1x10 0x10 means eleven samples of 1 (up for 5 minutes at 30-second steps), then 0. More on the format in the unit testing docs.
Alertmanager routing
Pages go to PagerDuty, tickets go to Slack, the Watchdog goes to the heartbeat service. Secrets are read from files, so the config itself can live in Git:
yaml
1route:2 receiver: team-tickets3 group_by: [alertname, service]4 group_wait: 30s5 group_interval: 5m6 repeat_interval: 4h7 routes:8 - matchers:9 - severity="heartbeat"10 receiver: deadmans-switch11 group_wait: 0s12 group_interval: 1m13 repeat_interval: 1m14 - matchers:15 - severity="page"16 receiver: oncall-pager17 repeat_interval: 1h18
19inhibit_rules:20 - source_matchers:21 - severity="page"22 target_matchers:23 - severity="ticket"24 equal: [service]25
26receivers:27 - name: oncall-pager28 pagerduty_configs:29 - routing_key_file: /etc/alertmanager/secrets/pagerduty-routing-key30 send_resolved: true31
32 - name: team-tickets33 slack_configs:34 - api_url_file: /etc/alertmanager/secrets/slack-webhook-url35 channel: "#alerts"36 send_resolved: true37 title: '{{ .CommonLabels.alertname }} ({{ .Status }})'38 text: '{{ range .Alerts }}{{ .Annotations.summary }}{{ "\n" }}{{ end }}'39
40 - name: deadmans-switch41 webhook_configs:42 - url_file: /etc/alertmanager/secrets/heartbeat-url43 send_resolved: falseCreate the three secret files with your own values. The heartbeat URL is the ping URL of a check in Healthchecks or a similar service:
shell
1mkdir -p alertmanager/secrets2printf '%s' 'YOUR_PAGERDUTY_ROUTING_KEY' > alertmanager/secrets/pagerduty-routing-key3printf '%s' 'https://hooks.slack.com/services/YOUR/WEBHOOK/URL' > alertmanager/secrets/slack-webhook-url4printf '%s' 'https://hc-ping.com/YOUR-CHECK-UUID' > alertmanager/secrets/heartbeat-urlDon't commit the secrets/ folder. For a dry run without real accounts, point all three receivers at any local HTTP endpoint that logs requests. That's how we tested this config.
Logs with the OpenTelemetry Collector and Loki
The collector tails Docker's JSON log files, parses them and sends them to Loki over OTLP:
yaml
1receivers:2 file_log:3 include:4 - /var/lib/docker/containers/*/*-json.log5 include_file_path: true6 start_at: end7 operators:8 - type: container9 format: docker10 add_metadata_from_filepath: false11
12processors:13 batch: {}14 resource:15 attributes:16 - key: service.name17 value: docker18 action: upsert19
20exporters:21 otlp_http/loki:22 endpoint: http://loki:3100/otlp23
24service:25 pipelines:26 logs:27 receivers: [file_log]28 processors: [resource, batch]29 exporters: [otlp_http/loki]In Kubernetes you'd run the collector as a DaemonSet and add the k8sattributes processor, so every log line gets its namespace, pod and container labels.
Grafana data sources
Grafana reads its data sources from a provisioning file:
yaml
1apiVersion: 12datasources:3 - name: Prometheus4 uid: prometheus5 type: prometheus6 url: http://prometheus:90907 isDefault: true8 - name: Loki9 uid: loki10 type: loki11 url: http://loki:310012 - name: Alertmanager13 uid: alertmanager14 type: alertmanager15 url: http://alertmanager:909316 jsonData:17 implementation: prometheusValidate before you start
Check every config with the same binaries that will run it. No local install needed:
shell
1docker run --rm -v "$PWD/prometheus:/etc/prometheus:ro" --entrypoint promtool \2 prom/prometheus:v3.15.1 check config /etc/prometheus/prometheus.yml3
4docker run --rm -v "$PWD/prometheus:/etc/prometheus:ro" -w /etc/prometheus/tests \5 --entrypoint promtool prom/prometheus:v3.15.1 test rules alerts_test.yml6
7docker run --rm -v "$PWD/alertmanager:/etc/alertmanager:ro" --entrypoint amtool \8 prom/alertmanager:v0.34.2 check-config /etc/alertmanager/alertmanager.ymlcheck config also checks the rule files it references. You should see SUCCESS for each command.
amtool can also show which receiver an alert with given labels would reach:
shell
1docker run --rm -v "$PWD/alertmanager:/etc/alertmanager:ro" --entrypoint amtool \2 prom/alertmanager:v0.34.2 config routes test \3 --config.file=/etc/alertmanager/alertmanager.yml severity=page service=shopshell
1oncall-pagerStart the stack and break something
Start everything and give it a minute:
shell
1docker compose up -d2docker compose psOpen Prometheus at localhost:9090/targets. All targets should be up. Note that both blackbox targets show up even if a probe fails: up only means blackbox_exporter answered. The probe result is in probe_success.
You can run a probe by hand to see what blackbox_exporter checks:
shell
1docker compose exec prometheus wget -qO- \2 'http://blackbox:9115/probe?module=http_2xx&target=http://shop/' | grep -E '^probe_(success|http_status_code)'shell
1probe_http_status_code 2002probe_success 1Now take the shop down:
shell
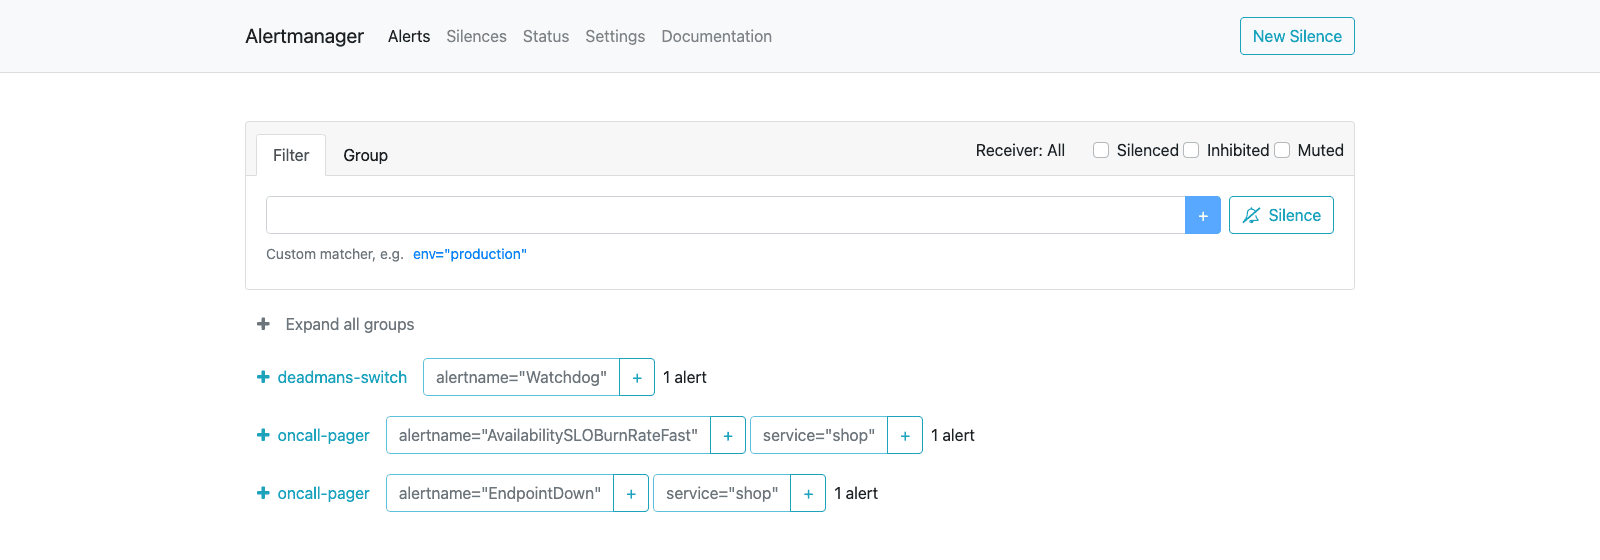
1docker compose stop shopWithin a minute the burn-rate alert fires, and after 2 minutes EndpointDown joins it. Both route to oncall-pager. The ticket-level burn-rate alert fires too, but Alertmanager suppresses it because a page for the same service is already active. Check it from the command line:
shell
1docker compose exec alertmanager amtool alert query --alertmanager.url=http://localhost:9093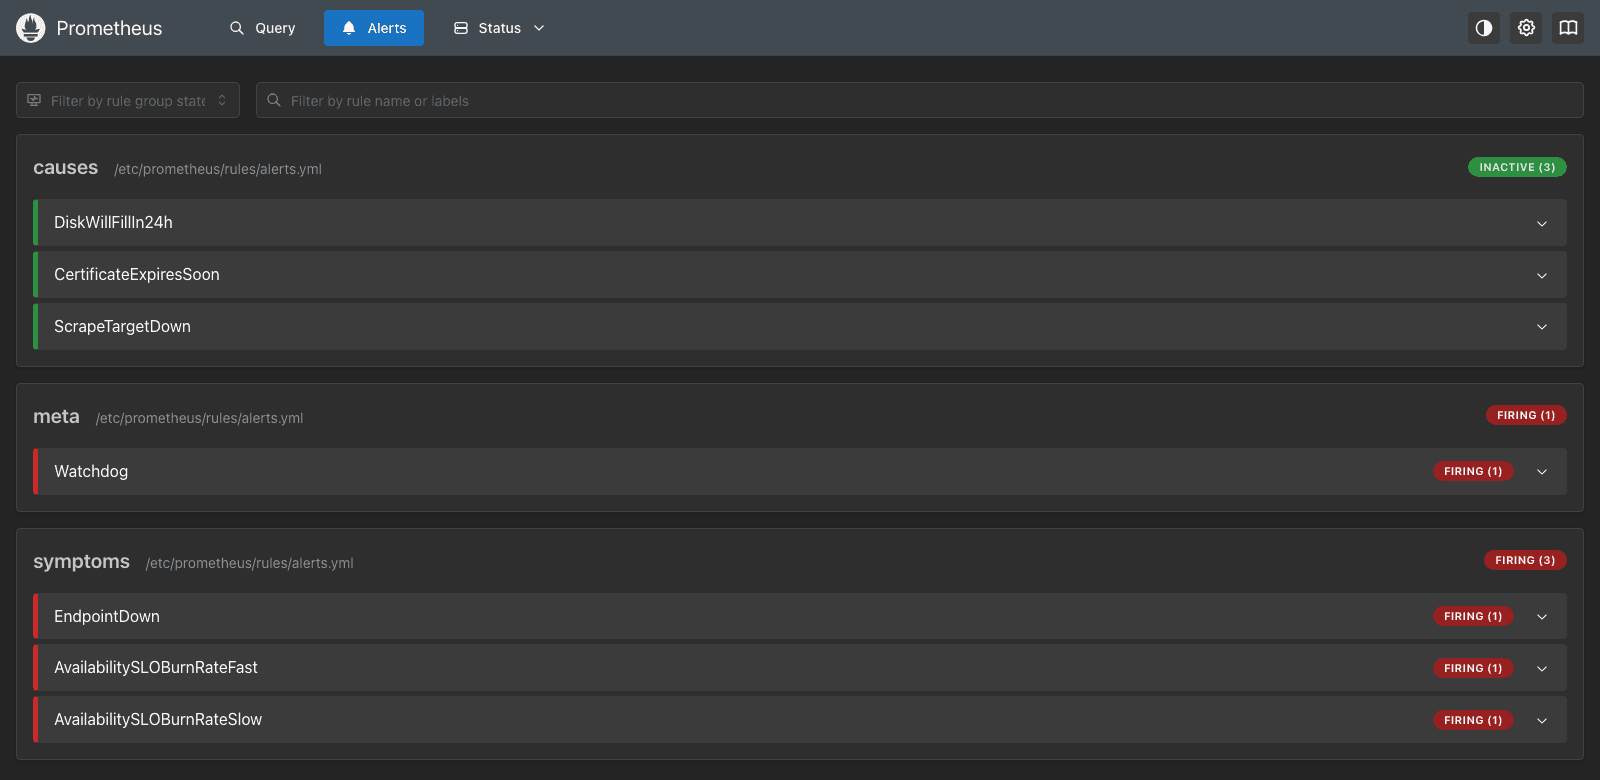
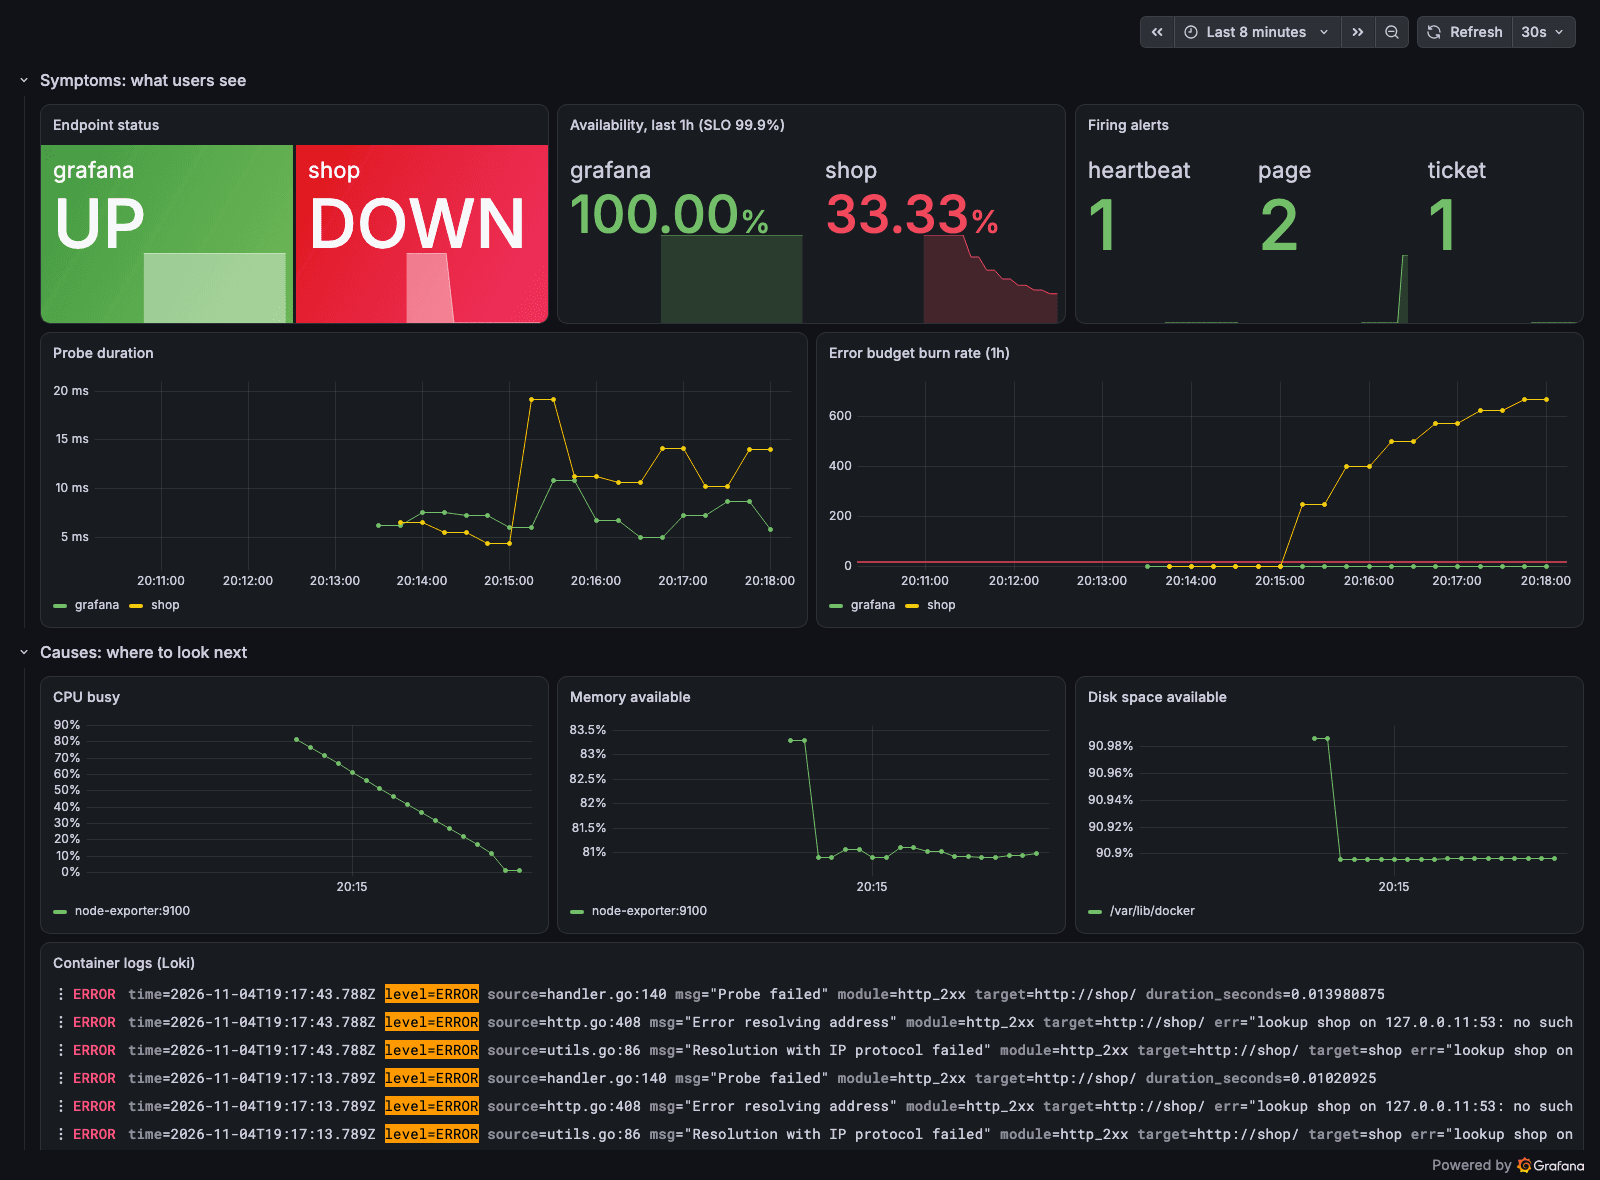
Log in to Grafana at localhost:3000 (user admin, the password from the Compose file) and open Explore with the Loki data source. The query {service_name="docker"} |= "Probe failed" shows blackbox_exporter's own log lines with the exact reason: the shop host doesn't resolve anymore. That's the "why" next to the "what".
Bring the shop back:
shell
1docker compose start shopEndpointDown resolves within a minute. The resolve event reaches PagerDuty with the next group update, up to 5 minutes later (group_interval). The burn-rate page takes longer: its 6-hour branch has a 30-minute short window, so it clears about half an hour after the last failed probe. That's on purpose. A service that has just burned a chunk of its budget isn't safe yet.
Only when the last page for shop resolves does Alertmanager release the inhibited ticket to Slack: the service lost part of its error budget, and someone should look at it in the morning.
When you're done:
shell
1docker compose down -vWrapping up
Good monitoring isn't about the number of graphs. It's about a few clear signals that users are in trouble, a pager people trust, and enough metrics, logs and traces to find the cause fast.
Start with SLOs for what users care about, page only on symptoms, send causes to tickets and dashboards, and review every page. The tools matter less than the discipline around them.
If you'd like a second pair of eyes on your monitoring, or someone to build and run it with you, take a look at our cloud engineering services or Kubernetes consulting.