What "scalable WordPress" actually means
On a single server, WordPress keeps its state in four places:
- the database (posts, users, options);
- the file system (uploads, plugins, themes,
wp-config.php); - the object cache, which by default lives only for one request;
- the secret keys and salts in
wp-config.php, which sign login cookies.
Scaling WordPress means taking every one of those out of the web server. When no instance holds anything unique, any instance can answer any request, and Auto Scaling can add or kill instances without anyone noticing.
That's the whole idea. The rest of this article is how to do it on AWS and which details people usually miss.
The reference architecture
AWS described this setup in its whitepaper Best Practices for WordPress on AWS (PDF, 2021). AWS has taken the web version down and keeps the PDF for historical reference only, and its CloudFormation templates on GitHub are archived. The building blocks are still the current AWS services, so we use the same layout with today's options.
A request travels like this:
- Amazon Route 53 resolves the domain to a CloudFront distribution.
- Amazon CloudFront caches content at the edge. It pulls media and static files from Amazon S3 and dynamic pages from the load balancer.
- An Application Load Balancer (ALB) in public subnets spreads requests across the web servers.
- EC2 instances in an Auto Scaling group run WordPress in private subnets across at least two Availability Zones.
- The instances share files on Amazon EFS, keep the object cache in Amazon ElastiCache, and store data in Amazon Aurora MySQL (or RDS for MySQL in Multi-AZ).
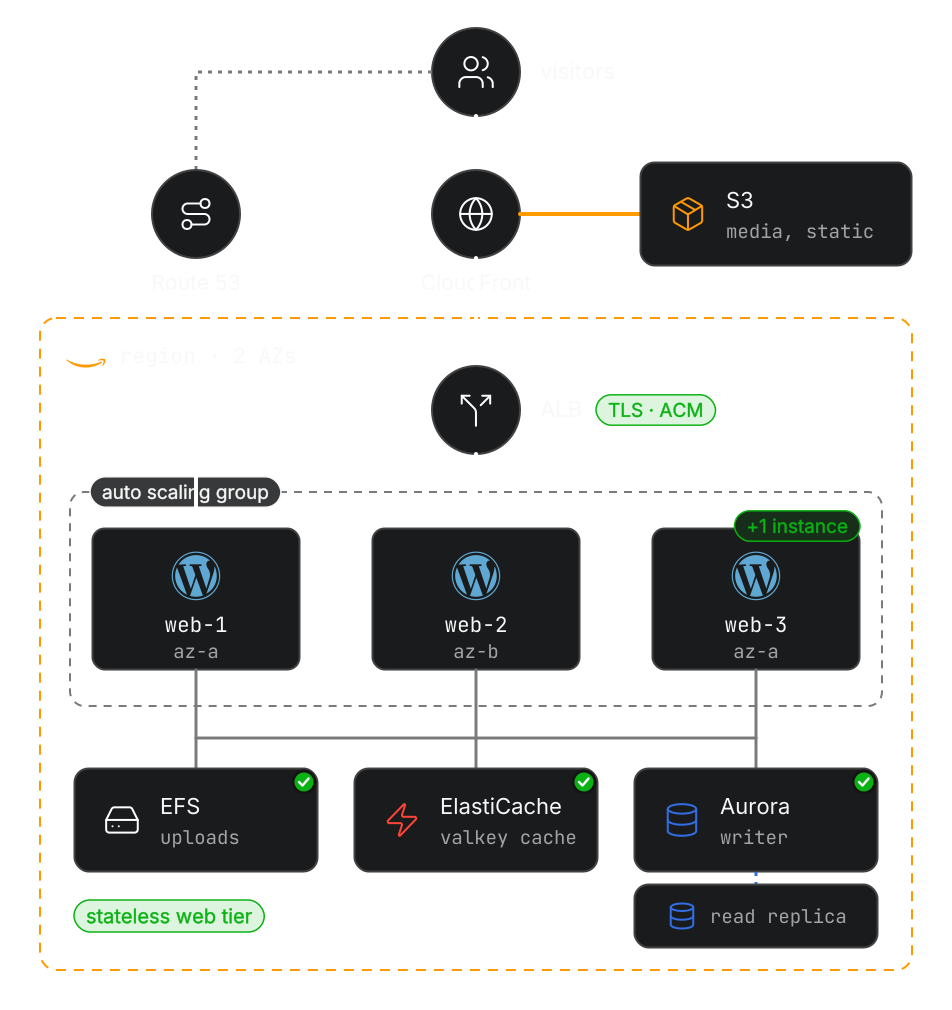
NAT gateways give the private instances outbound internet access for updates. The database, cache and file system have no public address at all.
DNS: Route 53
For a site in one AWS Region, a simple alias record from your domain to the CloudFront distribution is all you need.
Route 53 also has routing policies for multi-Region setups: latency-based routing sends users to the Region with the lowest latency, geolocation routing chooses by the user's location, and failover routing switches to a standby when health checks fail (routing policies). These only make sense once you run WordPress in more than one Region, which most sites never need.
CloudFront and S3: media and static files
CloudFront is a CDN, not storage. It keeps copies of files in edge locations close to users and fetches them from an origin when the copy is missing or expired.
The storage behind it is S3. A practical layout:
- Media and static files come from an S3 bucket. Keep the bucket private and let CloudFront read it through origin access control (OAC), which AWS recommends over the legacy OAI.
- Everything else goes to the ALB as the second origin.
/wp-admin/and/wp-login.phpget their own behavior with caching turned off.
Start by caching only static files and media at the edge. Caching HTML pages is possible too, but the cache policy has to take WordPress login cookies into account, otherwise logged-in users get anonymous pages or worse. Treat it as a separate project.
To move uploads to S3, WordPress needs a plugin. WP Offload Media Lite copies new uploads to the bucket and rewrites media URLs to your CloudFront domain. The free version handles only files uploaded after you turn it on. Moving an existing media library needs the paid version or a one-off sync.
If you don't want to offload media, keep uploads on EFS (see below) and let CloudFront cache them from the ALB. It's simpler, just a bit slower on cache misses.
Load balancing: Application Load Balancer
The ALB uses round robin by default: requests go to healthy targets evenly, in sequence. You can switch a target group to least outstanding requests or weighted random (routing algorithms). For WordPress, least outstanding requests often fits better, because a heavy admin page and a cached post page are very different amounts of work.
The ALB health check decides which instances get traffic. AWS suggests checking /wp-login.php, since it proves both the web server and PHP work. A custom health page that also checks the database and cache is better, as long as it's cheap to call.
Do you need sticky sessions?
For WordPress core, no. WordPress doesn't use PHP sessions for logins. It sets signed cookies, and any instance can check them, as long as every instance has the same keys and salts in wp-config.php.
We tested this on two WordPress nodes behind a round-robin load balancer. With different salts on each node, the user was logged out on every second request: one node accepted the cookie, the other rejected it. With identical salts, every request stayed logged in, without any stickiness.
Some plugins do store state in PHP sessions. If you have one, either point PHP sessions to Redis or Valkey, or enable ALB stickiness for that target group. Moving the state is the better fix, because stickiness makes scale-in and instance failures visible to users.
HTTPS ends at the load balancer
The usual setup terminates TLS on the ALB with an AWS Certificate Manager certificate and sends plain HTTP to the instances. WordPress then thinks the request is HTTP and can end up in a redirect loop.
The ALB tells the instance the original protocol in the X-Forwarded-Proto header (ALB headers). WordPress needs a few lines in wp-config.php to trust it. They're in the configuration section below.
Compute: EC2 Auto Scaling
EC2 Auto Scaling keeps the number of instances between a minimum and a maximum you set, spreads them across Availability Zones, replaces instances that fail health checks, and registers new instances with the load balancer (what Auto Scaling does). A target tracking policy on CPU (ASGAverageCPUUtilization) or on requests per instance (ALBRequestCountPerTarget) adds and removes instances as traffic changes.
What Auto Scaling doesn't do is synchronize anything. A new instance starts from the AMI and launch template, and that's all it knows. So:
- Ship WordPress core, themes and plugins in the image or with a deployment pipeline, and roll changes out with instance refresh.
- Turn off plugin and theme installs from the admin panel with
DISALLOW_FILE_MODS. Otherwise someone installs a plugin through the dashboard, it lands on one instance only, and the site behaves differently depending on which instance answers. We reproduced exactly that: a plugin installed and activated through one node was marked active in the database but not loaded on the other node. - Run WP-Cron from one place. By default WordPress runs scheduled tasks during page loads on whatever instance serves the request. Disable that with
DISABLE_WP_CRONand runwp cron event run --due-nowon a schedule from a single scheduler or a single instance (WordPress docs). - Reload PHP after each deploy. OPcache keeps compiled PHP files in memory. In our test, a node kept using its old
wp-config.phpafter the file was replaced, until PHP restarted.
Shared files: Amazon EFS
EFS is a managed NFS file system that every instance in every Availability Zone can mount. In this architecture it holds the files users create, mainly wp-content/uploads.
In our test, an image uploaded through one node was served by both nodes from the shared volume. A file written to one node's local disk returned a not-found response every time the other node answered. That's the exact failure EFS prevents.
Two things to know:
- Latency. EFS reads take about 1 ms and writes about 2.7 ms per operation in the best case (EFS performance). A local disk is much faster, and PHP touches dozens of files per request. That's why we keep WordPress code in the image and use EFS for uploads only. If you do put all of
wp-contenton EFS, size OPcache generously so PHP rarely hits the file system. - Settings. Use General Purpose performance mode and Elastic throughput; AWS recommends both for most workloads. Make sure the mounted directory is writable by the web server user. Our first upload failed with "Unable to create directory" because the shared volume was owned by root.
Object cache: Amazon ElastiCache
WordPress has an object cache, but out of the box it's non-persistent: it lives only for one request (WordPress docs). With several instances you want a shared, persistent cache, so a query one instance cached is a cache hit on all the others.
ElastiCache runs Valkey, Redis OSS or Memcached (ElastiCache engines). For WordPress we use a Valkey cluster with a replica in a second Availability Zone, and the Redis Object Cache plugin, which works with Valkey because Valkey speaks the Redis protocol.
In our test with Valkey 8.1, a value written to the cache on one node was read on the other, and an option changed through one node was immediately visible on the other.
The plugin also adds an object-cache.php drop-in to wp-content. Like any code, it has to be on every instance, so build it into the image.
Database: Aurora MySQL or RDS Multi-AZ
WordPress talks to MySQL. On AWS that's Aurora MySQL or RDS for MySQL. Both use one writer and optional read-only replicas.
The writer handles all writes, including many write transactions at the same time. The limit isn't "one write at a time". It's that all writes go to one node, so write capacity is the size of that node, while reads can scale out across replicas. For a typical WordPress site, which reads far more than it writes, that's fine.
Aurora MySQL
An Aurora cluster has one writer and up to 15 Aurora Replicas. The reader endpoint spreads connections across the replicas, replica lag is usually well under 100 ms, and if the writer fails, Aurora promotes a replica (Aurora replication, Aurora endpoints). Point WordPress at the cluster endpoint, not at an instance endpoint, so a failover doesn't need a config change.
RDS for MySQL
A Multi-AZ DB instance deployment has one standby for failover that doesn't serve reads. A Multi-AZ DB cluster has two standbys that serve reads too (Multi-AZ). You can add read replicas to either.
WordPress doesn't use replicas on its own
This is the part most guides skip. WordPress core sends every query to the single DB_HOST. In our test with plain WordPress, all 36 SELECT queries from six page loads went to the primary, and the replica got none.
To send reads to replicas, WordPress needs a database drop-in such as LudicrousDB, a maintained fork of Automattic's HyperDB. With LudicrousDB configured, page loads sent their reads to the replica, while writes went to the primary. After a write, LudicrousDB also sends further reads of that table in the same request to the primary, so a request can read what it just wrote.
It doesn't protect the next request. A user who saves a post and lands on a replica 50 ms later can briefly see the old version. Most sites get more from the object cache than from read replicas, so add replicas when database reads are the bottleneck, not by default.
Why we don't use master-master MySQL
Multi-master setups look attractive: two writable databases, no single writer. For WordPress they cause more problems than they solve. MySQL replication doesn't detect or resolve conflicts; the MySQL manual says this is left to the application (multi-source replication), and WordPress doesn't do it.
We ran two MySQL 8.4 nodes replicating to each other and wrote to both inside the replication delay:
- Same row updated on both nodes: each node applied the other's change. Node A ended with node B's value and node B with node A's. No error, the data simply diverged.
- Same unique key inserted on both nodes: replication stopped on both with a duplicate key error (1062) until someone fixed it by hand.
WordPress writes options, transients and counters all the time, so these collisions are not theoretical. One writer with replicas avoids the whole class of problems.
WordPress settings for this architecture
Everything below goes into wp-config.php, identical on every instance. Keep the real values out of Git, for example in AWS Secrets Manager or SSM Parameter Store, and render the file when you build the image.
Generate one set of keys and salts and use it everywhere:
shell
1curl -s https://api.wordpress.org/secret-key/1.1/salt/Then add the settings for the load balancer, database, cache and deployments:
php
1// TLS ends at the ALB: trust the original protocol it sends.2if ( isset( $_SERVER['HTTP_X_FORWARDED_PROTO'] ) && strpos( $_SERVER['HTTP_X_FORWARDED_PROTO'], 'https' ) !== false ) {3 $_SERVER['HTTPS'] = 'on';4}5
6// Aurora cluster (writer) endpoint and reader endpoint.7define( 'DB_HOST', 'wordpress.cluster-abc123.eu-west-1.rds.amazonaws.com' );8define( 'DB_READER_HOST', 'wordpress.cluster-ro-abc123.eu-west-1.rds.amazonaws.com' );9
10// ElastiCache (Valkey) for the Redis Object Cache plugin.11define( 'WP_REDIS_HOST', 'wordpress-cache.abc123.ng.0001.euw1.cache.amazonaws.com' );12define( 'WP_REDIS_PORT', 6379 );13define( 'WP_REDIS_PREFIX', 'mysite:' );14
15// Code comes from the image, not from the dashboard.16define( 'DISALLOW_FILE_MODS', true );17
18// WP-Cron runs from one scheduler, not on page loads.19define( 'DISABLE_WP_CRON', true );If in-transit encryption is enabled on the ElastiCache cluster, also add define( 'WP_REDIS_SCHEME', 'tls' );.
DB_READER_HOST is our own constant for LudicrousDB. Its db-config.php file sits next to wp-config.php and describes both servers:
php
1<?php2defined( 'ABSPATH' ) || exit;3
4$wpdb->charset = 'utf8mb4';5$wpdb->collate = 'utf8mb4_unicode_520_ci';6$wpdb->save_queries = false;7$wpdb->persistent = false;8$wpdb->max_connections = 10;9$wpdb->check_tcp_responsiveness = true;10
11// Writer: all writes, and reads only if no reader answers.12$wpdb->add_database( array(13 'host' => DB_HOST,14 'user' => DB_USER,15 'password' => DB_PASSWORD,16 'name' => DB_NAME,17 'write' => 1,18 'read' => 2,19) );20
21// Reader: Aurora reader endpoint or an RDS read replica.22$wpdb->add_database( array(23 'host' => DB_READER_HOST,24 'user' => DB_USER,25 'password' => DB_PASSWORD,26 'name' => DB_NAME,27 'write' => 0,28 'read' => 1,29) );LudicrousDB itself goes to wp-content/plugins/ludicrousdb, and its db.php drop-in to wp-content/db.php. Skip this file and the constant if you don't use read replicas.
Finally, the cron job. Run it from one place only, every minute or every five minutes:
shell
1wp cron event run --due-now --path=/var/www/htmlThese settings make WordPress scale, they don't make it secure. Hardening is a separate checklist, covered in our WordPress security hardening guide.
How to check that it really scales
Before you trust the setup, run the same checks we did. They take ten minutes and catch most mistakes:
- Logins. Log in and reload
/wp-admin/ten times. If you get logged out now and then, the salts differ between instances. - Uploads. Upload an image and request it through each instance directly. A not-found response from one of them means uploads aren't on shared storage.
- Cache. Run
wp cache set test 1on one instance andwp cache get teston another. The second command must return 1. - Plugins. Compare
wp plugin liston two instances. Any difference means code is changing outside your deployment process. - Replicas. If you use read replicas, check that the reader instances actually get queries, for example in their CloudWatch metrics for connections and CPU.
When you don't need all this
This architecture pays off for sites with real traffic, traffic spikes or uptime requirements. It also costs more than one server: a load balancer, NAT gateways, a database cluster and a cache cluster all bill around the clock, even at night.
For a small site, a single well-sized server with backups is often the better choice. Our Amazon Lightsail review covers that option. If you want to see the multi-node pattern on your own machine first, our guide on scaling a PHP application across several nginx Docker nodes builds a small version locally.
Planning WordPress on AWS?
Since 2014, ITsyndicate has been building and running infrastructure for web applications. Our cloud engineering team can design the WordPress setup for your traffic and budget, or move an existing site to AWS without downtime. Contact us to talk it through.
Already on AWS and not sure the setup is right? A cloud infrastructure review shows what to fix first.