What are the services you're paying for?
Real-life analogy
"Why do I need system admins or DevOps? Where does my money go if everything is already working as I need it to?"
Rly..?) Let’s do some analogy stuff and imagine that you’re watching a play in a theater. The play is great, the cast is just outstanding and marvelous, the scenario is mind-blowing and really exciting, it’s so good that it keeps everybody on their toes, the director's work is brilliant and the ending will tear your heart into pieces, and then put it back together. Imagined it, didn’t you?
I bet that you’ve painted a very bright picture in your head: a huge theater with great lighting; beautiful decorations; really good sound, including microphones you don’t need to hold in your hands, those badass low-profile mics with tiny headsets; an invisible prompter's box and a huge, wisely designed hall, so the people sitting at the back can easily see and hear what’s happening on the stage without binoculars or hearing aids :)
The only thing is that nobody considers that all these additional features are one of the main parts of the play. If we disable and exclude all of the above, the play will just become a bunch of famous people in costumes, throwing some well-rehearsed words and phrases at each other on the stage. The play is a complex thing, which consists of the actors’ work, the scenario, etc. as well as the lighting, sound, prompter's work, etc.
Actual DevOps role
So let’s get back to our IT world and try to compare the above statements with it. Actors are developers, who are working on creating/adjusting scenarios and the quality of the product. They develop scenarios together with the client/owner, which users will follow to interact with the system. They work on an understandable, clear, and easy-to-use design, so users can enjoy interacting with the system.
System administrators and DevOps engineers are working backstage: they adjust the light and turn it on / off when it’s needed / not needed, so end users can see the results of the developers' work. They also monitor the quality of the sound and its delivery to every user, and change the decorations at the back, so the end user can see other system features.
The ideal play is when all the gears of the mechanism are working smoothly and in a coordinated manner, so when something new appears on the stage, the light is automatically adjusted, and so is the sound.
And if anything goes wrong, for example, the sound doesn’t work, the techs need to catch the issue, which can be caused by:
- a mic that's just broken;
- a central sound processor that burnt itself down, so no one receives any sound.
And they need to understand the reason for it. There might be several options, some of them are:
- it broke due to an internal failure, aka the server got overloaded, and it’s a bottleneck that nobody considered during the initial discussion;
- an actor, aka a developer, just spilled coffee on the mic during the break, aka added non-working code, which has broken the functionality of certain components or of the whole system.
Real-life: "I want a single fix"
Real-life analogy
"I want a single fix and don’t need your support, monitoring, and stuff! My goal is to solve the problem ASAP, so it won’t appear anymore!"
Ha-ha..) Frankly speaking, the above statement is a real quote from one of the chats with one of our potential clients. Let’s get back to analogies.
So imagine that you came to the store to get yourself a brand-new car. Your friends and other buyers told you how awesome, super-fast and comfortable it is. The engine is something cosmic with around 500 horsepower, there's an onboard computer with climate control, etc. But during the sale nobody will tell you that this girl needs a lot of expensive engine oil, only top-quality gasoline, and, for comprehensive and correct operation, regular maintenance every six months, right?
Only people who had previous experience with buying cars and felt all those untold ‘BUTs’ on their own skin would consider the above points and think in advance about how to set up and get all of that working.
Many clients in the modern IT market don’t consider such issues and face problems like:
- I bought a car, it’s awesome! I was riding dirty, but now there’s some strange sound under the hood.
- Well, do I really need to do maintenance every six months? But why, if it’s working fine?
- I was doing some drift, skr-skr-skr-bang you know :) And now when I try to brake, I feel that I don’t have any grip on the road.
- Also, I put mid-grade gasoline instead of premium, is that ok?
- Why do I need to change the oil? I’ve already filled it, no need to change it!
How it usually happens
Reading all of the above is funny, right? Now I’ll try to do some analogy stuff with our area of work: the client hired developers, who developed a great website with an outstanding design and showed how it all works on their LOCAL MACHINE, let’s call it some kind of test drive. The client approved everything, so they closed the contract, and a happy client got what he paid for. He even got instructions on how to deploy his code to the server. WOW! :)
So the happy client comes home thinking: “Now I’ll do some stuff on my brand new car!”, and deploys the site to the server following the instructions. He/she launches it and everything is working fine. People begin visiting it, as he/she posted information about the new website on every social network profile he/she has. Several days pass by, and all is just fine, but suddenly… something is wrong. The site is slow, then users start complaining about randomly appearing errors, and then the site just stops working correctly at all.
So what happened? In many cases, we face a handoff process that didn't finish correctly, as the client didn’t have enough information about the required specs, metrics, hardware, etc. Nobody told him/her about them, just like no one told the happy car buyer that this baby needs regular maintenance every six months.
Actual maintenance role
Server maintenance is a complex thing consisting of numerous actions that are done to prevent errors from happening and to deal with them at their source before they become a real problem. So what should you consider in order to run your business without any issues? Most of it is listed below. Each point is very important, and ignoring even a single one of them can cause problems that might evolve into a loss of money, revenue, or even sensitive business data.
Server specs required for the correct operation of a website/app
Testing that was run on a single local machine (don’t take these words as a generalization about every development studio and freelance developer; we encounter fewer and fewer such cases, but they’re still around) with a single user in the DB and without any load went fine and without any errors. But in no case can we say that it simulates the real system’s behavior! Sadly, only a few understand it, but I meet more and more technically savvy people. Or just people who teach themselves on their own mistakes :D
Logs and server/website monitoring
How can you catch what happened to your server/website if it began to slow down or just went down for no reason? And how can you prevent such a situation from happening in the future? You can find the answers to these questions in our article about proper monitoring system organization.
Backups - one of the most important components in any non-commercial and commercial project
What will you do if:
- your server degraded?
- your database is down?
How will you restore normal operation of your online project? How will you roll back to a certain state of the system if you need to? The answer to all of the previous questions is the same: restore it from a backup.
Server overload during traffic spikes
How are you going to take care of the server so it won't get overloaded at all? And how do you implement this so that the live customers currently visiting your site won’t even notice the change? Btw, that’s just what our clients usually ask us to do: zero downtime.
Website / server / software updates
Timely updates close most of the doors attackers actually use. Exploiting known, already-patched vulnerabilities is one of the most common ways in, and Verizon's Data Breach Investigations Report puts it among the top entry points year after year. The biggest backdoor, and you’ll laugh, the easiest one, is an open vulnerability or bottleneck in an old software version. Why do you think developers of the products and tools we use constantly deliver new patches and modifications? Because hacking never sleeps...)
So, about that single fix
Now let’s get back to the beginning of this topic: “I want a single fix!”. Then I have a single question: why do you even need to bring it to the point where fixing is necessary? What’s the point of waiting and saving costs on the things you think are not important? And then paying for the “single fix” anyway and bearing the losses caused by the issue?
In fact, everything can be designed, as I like to say, with the BEST PRACTICE approach from scratch. The only work that's unavoidable after successful delivery is infrastructure support and maintenance, preventing problems from happening or dealing with them quickly, as the support team will catch and track them almost instantly.
Now let me explain why a single fix can or cannot solve the problem once and for all... Unfortunately, many problems can’t be solved once and for all. They can’t even be called problems, they are more related to the system’s maintenance, just like the maintenance of a car from time to time.
Solving such issues can be automated, but not in all possible cases. Our team has implemented some cool and fully independent solutions, which allow the system to clean up its own mess where it’s possible.
The misery caused by misunderstandings
How it usually is
"My developers didn’t do anything wrong, they showed me the working solution, and I tested it! That’s definitely a server issue - deal with it!"
These words are fundamentally wrong. The phenomenon you see here we call a virtual wall: when developers don’t understand what we want, and DevOps don’t understand what developers want.
This is what happens:
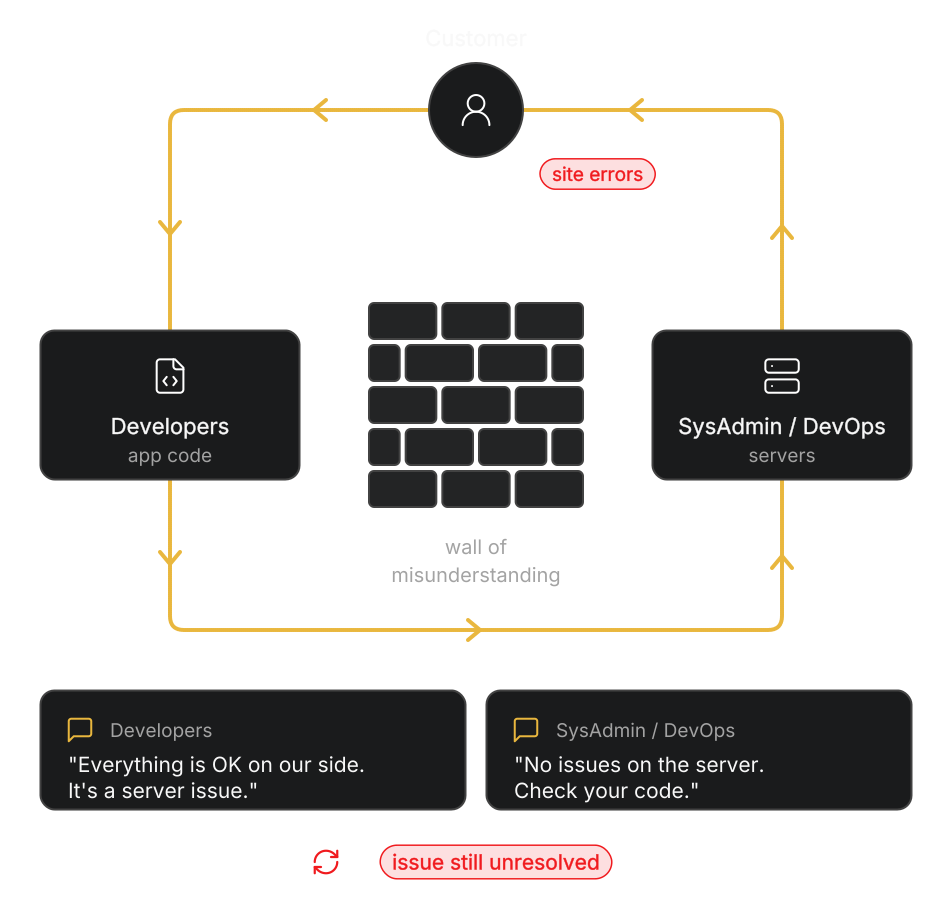
I think there is no need to explain the above schema, as everything is pretty straightforward there. Let me give you an example of a workflow that will eliminate:
- client’s dissatisfaction;
- decreasing trust in developers and DevOps;
- fails and errors when deploying to prod;
- client’s money loss.
How it should be
The DevOps workflow you can see below has proved itself on many of our projects, which were successfully delivered and deployed live. The client’s satisfaction was through the roof, and he was happy to collaborate more.
The main point is that problems can’t always be on one side. I can compare the interaction between developers and system admins / DevOps engineers with a scale. It's in balance only when both pans hold the same amount of weight.
Same here - harmony and balance in any project begin when the efforts and work of both teams are fully coordinated with each other.
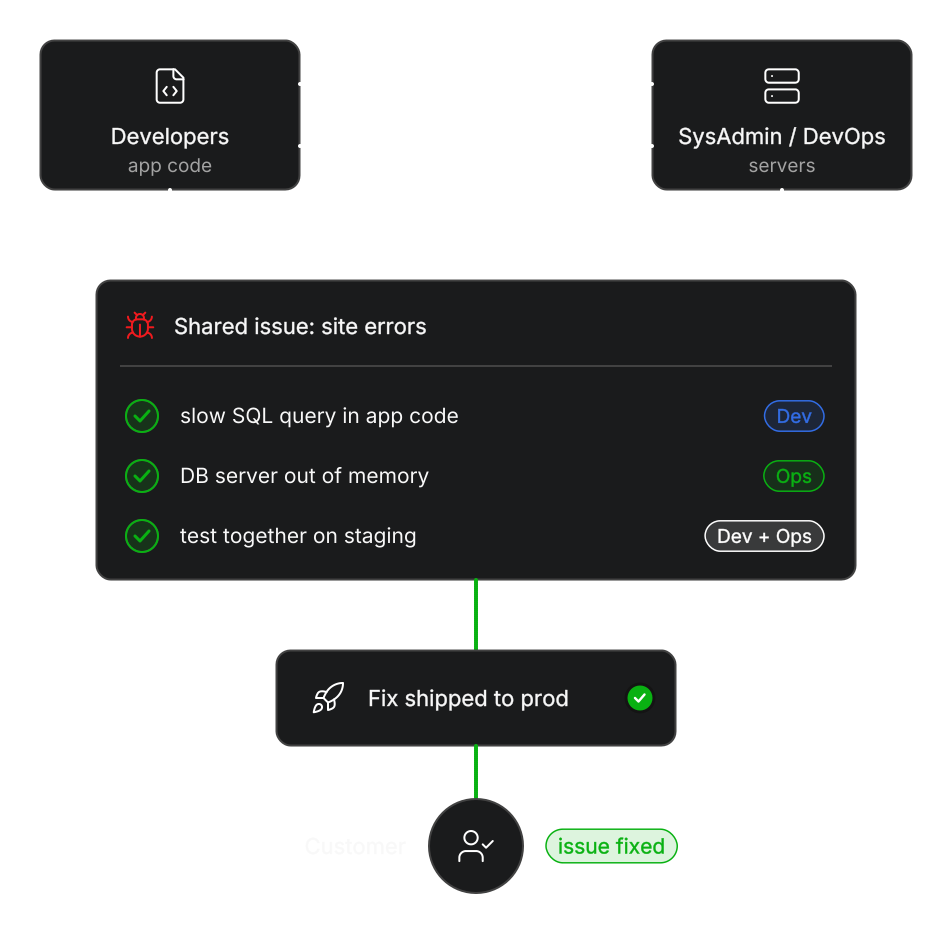
In this blog post, I could give you more and more cases, but I’d like to draw a conclusion from all of the above: harmony is achieved when all mechanisms of the project are working together and helping each other fix their own and other people’s mistakes.
An understanding client will be nothing but happy with the speed and efficiency of problem-solving, as every side of the mechanism follows and considers the wishes, recommendations, and instructions provided by the other side (-s). And he will also be happy that the developers team and the DevOps team enjoy working together and delivering something outstanding and cool!
Also, I’d like to mention that sometimes the performance of the mechanism isn’t clear and obvious, just like the adjustments made to the light/sound/decorations on the stage, but that doesn’t mean it doesn’t do any work. It just means that the work is done in the background, almost unnoticed by the system and the client.
Let’s get along! Mutual understanding leads only to positive results!
More to come..)