A PHP app on one server is easy. Code, uploads, sessions and cron all live on the same disk, so everything just works.
Add a second server and the hidden state shows up. A file uploaded on node 1 returns 404 on node 2. Users get logged out at random. Cron runs twice. A frozen PHP-FPM process keeps getting traffic.
This guide builds a setup that handles all of that, step by step. WordPress is the example because it has every one of these problems, but the same design works for Laravel, Symfony or plain PHP.
Tested with Docker Engine 29.9 in Swarm mode, WordPress 7.1, PHP 8.4, NGINX 1.30, MariaDB 11.8 and Redis 8.6, with an NFS server on Ubuntu 24.04.
Why Docker Swarm
You have three realistic ways to run several PHP containers behind NGINX:
- Docker Compose with
--scaleruns replicas on one host. It's good for local testing, but one host is still one point of failure, so it doesn't solve the problem. - Docker Swarm is built into Docker Engine. You turn a few servers into a cluster with two commands and deploy a Compose-style file to it. It's the shortest path from "one Docker server" to "several Docker nodes".
- Kubernetes gives you autoscaling, a bigger ecosystem and managed offerings in every cloud, at the cost of more moving parts. If you already run Kubernetes, see the section on Kubernetes at the end.
This guide uses Swarm. Everything about state (files, sessions, salts, cron, health checks) applies to Kubernetes the same way.
Architecture
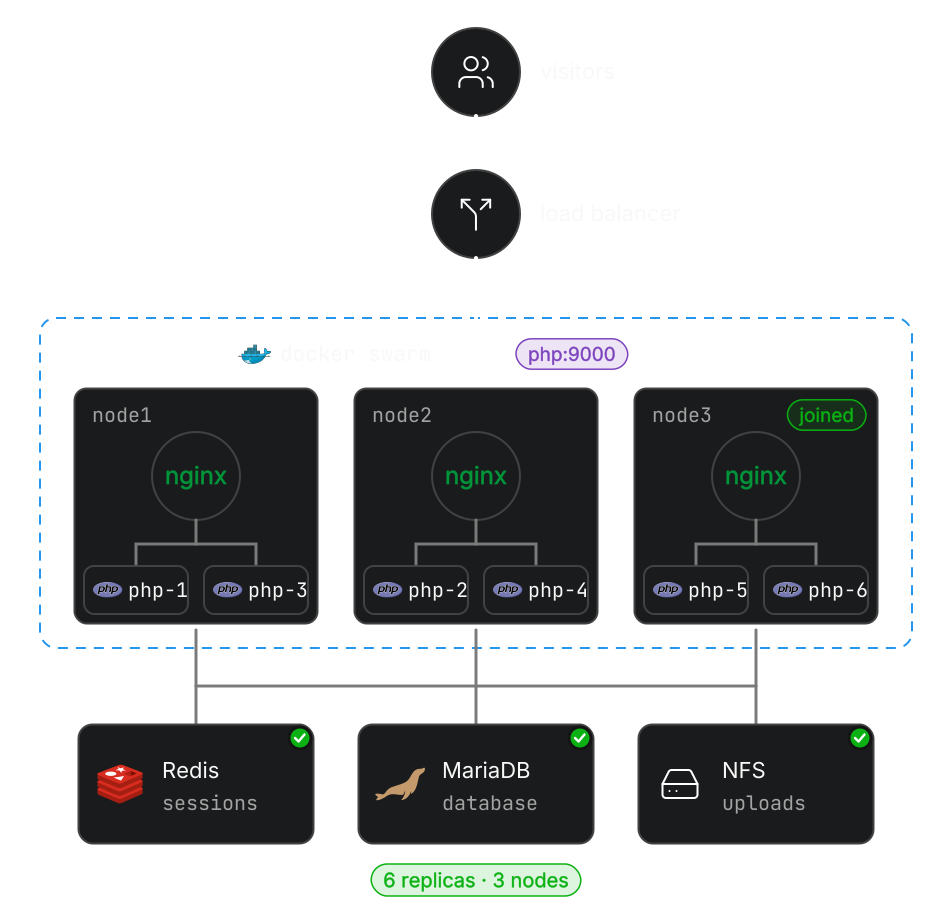
- Load balancer or DNS. Sends visitors to the nodes. A cloud load balancer with a health check is the best option, round-robin DNS works for a start.
- NGINX, one container per node. It serves static files and passes PHP requests to PHP-FPM.
- PHP-FPM, as many replicas as you need, spread across the nodes. NGINX reaches them through one service name, and Swarm balances the connections.
- NFS server for
wp-content/uploads, the only directory WordPress writes to at runtime. - Redis for PHP sessions, so a session started on one replica works on all of them.
- MariaDB, one instance. In production, a managed database is better.
- Cron, one container that runs WordPress scheduled tasks, so they run exactly once.
Code, themes and plugins are baked into the Docker image. Nothing in the code directory is shared or changed at runtime, which is what lets you run any number of copies.
The example uses this network:
10.0.0.10- NFS server;10.0.0.11-node1, Swarm manager;10.0.0.12-node2, worker;10.0.0.13-node3, added later to show scaling out.
Use private IPs for all traffic between servers, and put the nodes behind a firewall.
Step 1: Prepare the nodes
Install Docker Engine on every node from Docker's apt repository, following the official guide for Ubuntu. Use the same Docker version on all nodes.
Open these ports between the nodes, on the private network only:
2377/tcp- Swarm cluster management, to the manager nodes;7946/tcpand7946/udp- node discovery;4789/udp- overlay network traffic (VXLAN);80/tcp- from your load balancer to every node.
The NFS server needs 2049/tcp open to the nodes.
Step 2: Set up the NFS server
On the NFS server (10.0.0.10), install the NFS server and create the shared directory:
shell
1sudo apt-get update2sudo apt-get install -y nfs-kernel-server3sudo mkdir -p /srv/nfs/wp-uploads4sudo chown www-data:www-data /srv/nfs/wp-uploadsExport it to the private network only:
shell
1echo "/srv/nfs/wp-uploads 10.0.0.0/24(rw,sync,no_subtree_check,all_squash,anonuid=33,anongid=33,fsid=0)" | sudo tee -a /etc/exports2sudo exportfs -ra3sudo systemctl restart nfs-kernel-server4sudo exportfs -vWhat the options do:
all_squash,anonuid=33,anongid=33- every client writes as user 33. That'swww-databoth on Ubuntu and in the official WordPress image, so file ownership always matches. It also means root on a client is not root on the share, unlike the riskyno_root_squash.fsid=0- makes this directory the NFSv4 root, so clients mount it as/.sync- the server confirms a write only after it reaches the disk.
On every node, install the NFS client and check that the share mounts:
shell
1sudo apt-get install -y nfs-common2sudo mount -t nfs4 10.0.0.10:/ /mnt3sudo touch /mnt/test-from-$(hostname) && ls -ln /mnt4sudo rm /mnt/test-from-$(hostname) && sudo umount /mntThe file should belong to 33 33. You don't need to keep the share mounted on the hosts: Docker mounts it for the containers.
Step 3: Create the Swarm
On node1:
shell
1docker swarm init --advertise-addr 10.0.0.11 --default-addr-pool 10.20.0.0/16⚠️ Don't skip --default-addr-pool if your servers live in 10.x. By default, Swarm takes subnets for its overlay networks from 10.0.0.0/8.
In our test, the Swarm ingress network got 10.0.0.0/24, the same subnet as the servers, and traffic between nodes stopped: NGINX returned 502 with No route to host.
Pick any range that doesn't overlap your network. The pool can only be set when you create the Swarm.
The command prints a docker swarm join line with a token. Run it on node2:
shell
1docker swarm join --token <worker-token> 10.0.0.11:2377Back on node1, check the nodes and mark the one that will run the database:
shell
1docker node ls2docker node update --label-add db=true node1One manager is enough to follow this guide. For production, run three managers (docker node promote <node>), so the cluster survives the loss of one of them.
Step 4: Build the images
You need two images built from the same code: PHP-FPM runs the PHP files, NGINX serves the static files. Building both from one Dockerfile keeps them in sync.
Project layout:
shell
1mywp/2├── Dockerfile3├── stack.yml4├── nginx/5│ └── default.conf6├── php/7│ ├── redis-sessions.ini8│ └── zz-healthcheck.conf9└── src/10 ├── whoami.php11 └── wp-content/ # your themes, plugins and mu-pluginsThe Dockerfile
dockerfile
1# syntax=docker/dockerfile:12
3# PHP-FPM image: WordPress core + your themes and plugins4FROM wordpress:7.1-php8.4-fpm AS php5RUN apt-get update \6 && apt-get install -y --no-install-recommends libfcgi-bin \7 && rm -rf /var/lib/apt/lists/* \8 && pecl install redis \9 && docker-php-ext-enable redis10COPY /usr/local/bin/wp /usr/local/bin/wp11COPY php/redis-sessions.ini /usr/local/etc/php/conf.d/redis-sessions.ini12COPY php/zz-healthcheck.conf /usr/local/etc/php-fpm.d/zz-healthcheck.conf13# your code: themes, plugins, mu-plugins, test scripts14COPY src/ /usr/src/wordpress/15HEALTHCHECK \16 CMD SCRIPT_NAME=/ping SCRIPT_FILENAME=/ping REQUEST_METHOD=GET \17 cgi-fcgi -bind -connect 127.0.0.1:9000 | grep -q pong18
19# nginx image: the same code, so static files are served without PHP20FROM nginx:1.30 AS nginx21COPY /usr/src/wordpress /var/www/html22COPY nginx/default.conf /etc/nginx/conf.d/default.conf23HEALTHCHECK \24 CMD curl -fsS http://127.0.0.1/healthz || exit 1The PHP stage starts from the official WordPress image and adds:
- the phpredis extension for sessions;
- WP-CLI, for installing WordPress and running cron;
cgi-fcgi, so the health check can talk to PHP-FPM directly.
The official image keeps WordPress in /usr/src/wordpress and copies it to /var/www/html when a container starts. Your files from src/ go to the same place, so they are copied along with the core.
PHP settings
php/redis-sessions.ini stores sessions in Redis instead of local files:
shell
1session.save_handler = redis2session.save_path = "tcp://redis:6379"php/zz-healthcheck.conf turns on the PHP-FPM ping page used by the health check:
shell
1[www]2ping.path = /pingNGINX config
nginx/default.conf:
nginx
1upstream php {2 # "php" is the Swarm service name; its virtual IP balances between replicas3 server php:9000;4}5
6server {7 listen 80 default_server;8 server_name _;9 root /var/www/html;10 index index.php;11 client_max_body_size 64m;12
13 # shows which nginx replica answered14 add_header X-Served-By $hostname always;15
16 location = /healthz {17 access_log off;18 default_type text/plain;19 return 200 "ok\n";20 }21
22 location / {23 try_files $uri $uri/ /index.php?$args;24 }25
26 # never execute PHP from the shared uploads directory27 location ~* ^/wp-content/uploads/.*\.php$ {28 deny all;29 }30
31 location ~ \.php$ {32 try_files $uri =404;33 include fastcgi_params;34 fastcgi_param SCRIPT_FILENAME $document_root$fastcgi_script_name;35 fastcgi_pass php;36 }37
38 location ~* \.(css|js|png|jpe?g|gif|ico|svg|webp|woff2?)$ {39 expires 30d;40 access_log off;41 try_files $uri =404;42 }43}fastcgi_pass points to the service name php. Swarm gives every service a virtual IP and spreads connections across its healthy replicas, so you never list containers in the config and never edit it when you scale.
A test script
src/whoami.php shows which replica answered and counts requests in the session:
php
1<?php2// Test script: shows which PHP-FPM replica answered. Delete it in production.3header('Content-Type: text/plain');4session_start();5$_SESSION['hits'] = ($_SESSION['hits'] ?? 0) + 1;6echo 'php: ' . gethostname() . "\n";7echo 'session hits: ' . $_SESSION['hits'] . "\n";Build and push
All nodes pull images from a registry, so push them to yours. Replace registry.example.com/mywp with your registry and repository (Docker Hub, GitHub Container Registry, a cloud registry or your own):
shell
1cd mywp2docker login registry.example.com3docker build --target php -t registry.example.com/mywp/php:1.0 .4docker build --target nginx -t registry.example.com/mywp/nginx:1.0 .5docker push registry.example.com/mywp/php:1.06docker push registry.example.com/mywp/nginx:1.0Use a new tag for every release instead of overwriting latest. It makes updates and rollbacks predictable.
Step 5: Create secrets and WordPress salts
Store the database password as a Docker secret. Containers read it from a file, and it never shows up in docker inspect:
shell
1openssl rand -base64 24 | docker secret create wp_db_password -Now generate the WordPress keys and salts:
shell
1for k in AUTH_KEY SECURE_AUTH_KEY LOGGED_IN_KEY NONCE_KEY AUTH_SALT SECURE_AUTH_SALT LOGGED_IN_SALT NONCE_SALT; do2 echo "WORDPRESS_$k=$(openssl rand -hex 32)"3done > wp-salts.env4chmod 600 wp-salts.env⚠️ This step is easy to miss, and it breaks logins. WordPress signs login cookies with these salts. If you don't set them, the official image generates random ones in every container, so each replica has its own.
We tested it: after logging in, 6 of 8 requests to /wp-admin/ were sent back to the login page, because they landed on replicas that didn't recognize the cookie. With shared salts, 8 of 8 returned 200.
Keep wp-salts.env out of Git and back it up: changing the salts logs everyone out.
Step 6: Deploy the stack
stack.yml:
yaml
1services:2 nginx:3 image: registry.example.com/mywp/nginx:1.04 hostname: "nginx-{{.Node.Hostname}}"5 ports:6 - target: 807 published: 808 mode: host9 volumes:10 - uploads:/var/www/html/wp-content/uploads:ro11 networks: [web]12 deploy:13 mode: global14
15 php:16 image: registry.example.com/mywp/php:1.017 hostname: "php-{{.Task.Slot}}-{{.Node.Hostname}}"18 env_file: wp-salts.env19 environment: &wp-env20 WORDPRESS_DB_HOST: db21 WORDPRESS_DB_NAME: wordpress22 WORDPRESS_DB_USER: wordpress23 WORDPRESS_DB_PASSWORD_FILE: /run/secrets/wp_db_password24 WORDPRESS_CONFIG_EXTRA: |25 define('DISABLE_WP_CRON', true);26 define('DISALLOW_FILE_MODS', true);27 secrets: [wp_db_password]28 volumes:29 - uploads:/var/www/html/wp-content/uploads30 networks: [web]31 deploy:32 replicas: 433 resources:34 limits:35 memory: 512M36 update_config:37 parallelism: 138 order: start-first39 failure_action: rollback40
41 cron:42 image: registry.example.com/mywp/php:1.043 user: www-data44 entrypoint: ["docker-ensure-installed.sh"]45 command: ["bash", "-c", "while true; do wp cron event run --due-now; sleep 60; done"]46 env_file: wp-salts.env47 environment: *wp-env48 secrets: [wp_db_password]49 volumes:50 - uploads:/var/www/html/wp-content/uploads51 networks: [web]52 healthcheck:53 disable: true54 deploy:55 replicas: 156
57 redis:58 image: redis:8.659 networks: [web]60 deploy:61 replicas: 162
63 db:64 image: mariadb:11.865 environment:66 MARIADB_DATABASE: wordpress67 MARIADB_USER: wordpress68 MARIADB_PASSWORD_FILE: /run/secrets/wp_db_password69 MARIADB_RANDOM_ROOT_PASSWORD: "1"70 secrets: [wp_db_password]71 volumes:72 - db-data:/var/lib/mysql73 networks: [web]74 healthcheck:75 test: ["CMD", "healthcheck.sh", "--connect", "--innodb_initialized"]76 interval: 10s77 retries: 578 deploy:79 placement:80 constraints: [node.labels.db == true]81
82volumes:83 uploads:84 driver: local85 driver_opts:86 type: nfs87 o: "addr=10.0.0.10,nfsvers=4.2,rw,hard"88 device: ":/"89 db-data:90
91networks:92 web:93 driver: overlay94
95secrets:96 wp_db_password:97 external: trueThe important parts:
- NGINX runs in
globalmode with ahostport. You get exactly one NGINX per node, listening on port 80 of that node, and a new node gets its NGINX automatically. Withmode: host, NGINX sees the real client address. Through the default routing mesh, it would see an internal Swarm address instead (in our test,10.20.0.3). - Don't use
order: start-firstfor NGINX. With a host port, the new container can't bind port 80 while the old one still holds it, and the update gets stuck. The defaultstop-firstis right here. Point your load balancer health check at/healthzon each node so it skips a node during the restart. - The
uploadsvolume is NFS. Docker mounts the share from Step 2 on whichever node runs the container. PHP writes to it, NGINX reads from it. DISALLOW_FILE_MODSturns off installing and updating plugins and themes from the admin panel. A plugin installed through the browser would land on one replica only. Add plugins tosrc/wp-content/, build a new image and roll it out.DISABLE_WP_CRONstops WordPress from running cron on page views. Thecronservice runs it instead (more on that below).- PHP updates roll one replica at a time (
parallelism: 1), start the new container before stopping the old one (start-first), and roll back automatically if the new version fails to start. - The database runs only on the node labeled
db=true, so its local volume always stays on the same disk.
Deploy it from the directory with stack.yml and wp-salts.env:
shell
1docker stack deploy -c stack.yml --with-registry-auth --detach=false wp--with-registry-auth passes your registry login to the nodes so they can pull private images. --detach=false waits until the services are running.
On the first deploy, NGINX may restart a couple of times with host not found in upstream "php:9000" before the PHP service is ready. That's expected and stops on its own.
Check the result:
shell
1docker stack services wp2docker service ps wp_phpEvery service should show full replicas, like 4/4 for wp_php and 2/2 for the global wp_nginx.
Step 7: Install WordPress
Run WP-CLI in any PHP container. docker exec works only on the node where the container runs, so run this on a node that has a wp_php task:
shell
1docker exec -u www-data $(docker ps -q -f name=wp_php | head -n1) \2 wp core install --url=http://wp.example.com --title="My site" \3 --admin_user=admin --admin_password='<strong-password>' \4 --admin_email=admin@example.com --skip-emailIf your load balancer terminates HTTPS, use the https URL and make sure the balancer sends the X-Forwarded-Proto: https header. The wp-config.php generated by the official image already reads it, and NGINX passes it to PHP.
Step 8: Check that it works
Load balancing and sessions
Send a few requests with one cookie, alternating between nodes:
shell
1for i in 1 2 3 4 5 6; do2 ip=10.0.0.1$(( (i % 2) + 1 ))3 curl -s -c /tmp/jar -b /tmp/jar -D /tmp/headers -H "Host: wp.example.com" http://$ip/whoami.php | tr '\n' ' '4 grep -i x-served-by /tmp/headers5doneOutput from our test:
shell
1php: php-1-node2 session hits: 1 X-Served-By: nginx-node22php: php-1-node2 session hits: 2 X-Served-By: nginx-node13php: php-4-node2 session hits: 3 X-Served-By: nginx-node24php: php-4-node2 session hits: 4 X-Served-By: nginx-node15php: php-2-node1 session hits: 5 X-Served-By: nginx-node26php: php-2-node1 session hits: 6 X-Served-By: nginx-node1Both NGINX containers answer, requests reach PHP replicas on both nodes, and the session counter keeps growing. If sessions were stored in local files, the counter would reset every time the request hit another replica.
Session handling matters for any PHP app that uses session_start(), including many WordPress plugins. WordPress core itself doesn't use PHP sessions: it keeps logins in cookies, which is why the salts from Step 5 matter.
Shared uploads
Upload a file through one replica:
shell
1docker exec -u www-data $(docker ps -q -f name=wp_php | head -n1) \2 wp media import https://s.w.org/style/images/about/WordPress-logotype-standard.png --porcelain=urlThe command prints the file URL. Request it through every node:
shell
1curl -s -o /dev/null -w "%{http_code}\n" -H "Host: wp.example.com" http://10.0.0.11/wp-content/uploads/<year>/<month>/WordPress-logotype-standard.png2curl -s -o /dev/null -w "%{http_code}\n" -H "Host: wp.example.com" http://10.0.0.12/wp-content/uploads/<year>/<month>/WordPress-logotype-standard.pngBoth return 200, and the file is on the NFS server in /srv/nfs/wp-uploads, owned by user 33. A PHP file placed in uploads returns 403 thanks to the deny rule in the NGINX config.
Step 9: Scale out
Add replicas
shell
1docker service scale wp_php=6Add a node
Join a new server the same way as node2. Get the command on the manager:
shell
1docker swarm join-token workerRun the printed docker swarm join command on node3. A few seconds later NGINX is running there too, because the service is global. Scale PHP up and the new replicas go to the least busy node, which is the new one:
shell
1docker service scale wp_php=82docker service ps wp_phpAdd the new node to your load balancer or DNS, and to the NFS export if it's outside 10.0.0.0/24.
Rebalance after a node failure
Swarm doesn't move running containers on its own. If a node was down or joined late, its replicas stay on the other nodes.
In our test, all four PHP replicas ended up on one node after the other one restarted. Spread them again with a rolling restart:
shell
1docker service update --force wp_phpHealth checks and zero-downtime updates
Both images have a HEALTHCHECK:
- PHP-FPM answers
pongon its ping page. A replica that stops answering is marked unhealthy after three failed checks, removed from balancing, and replaced. In our test, we froze all PHP-FPM processes in one container: about 40 seconds later Swarm killed it and started a new one. - NGINX answers on
/healthz.
To ship a new version, build and push a new tag, then update the service:
shell
1docker build --target php -t registry.example.com/mywp/php:1.1 .2docker build --target nginx -t registry.example.com/mywp/nginx:1.1 .3docker push registry.example.com/mywp/php:1.14docker push registry.example.com/mywp/nginx:1.15docker service update --image registry.example.com/mywp/php:1.1 wp_php6docker service update --image registry.example.com/mywp/nginx:1.1 wp_nginxOr change the tags in stack.yml and run docker stack deploy again. When we updated eight PHP replicas from 1.0 to 1.1 under constant load, we got 30,084 responses with 200 and not a single error.
⚠️ The PHP-FPM ping proves that PHP-FPM is alive, not that your code works. In our test, a release with a syntax error in a PHP file passed the health checks and rolled out to every replica. Test a new image before the rollout, and if something slips through, roll back with one command:
shell
1docker service rollback wp_phpPoint your load balancer health check at a page that runs PHP, such as a small status endpoint of your app, and not only at /healthz. Then a broken node stops getting traffic.
Cron in containers
With DISABLE_WP_CRON, WordPress no longer runs scheduled tasks on page views, which is better for busy sites. The cron service runs them instead:
- it uses the same image as PHP, so the code, extensions and settings are identical;
- it runs as a single replica, so every task runs once, not once per node;
- it calls
wp cron event run --due-nowevery 60 seconds and writes to the container log.
The docker-ensure-installed.sh entrypoint from the official image prepares WordPress and wp-config.php the same way as in PHP containers. The health check is off for this service because it doesn't run PHP-FPM.
See what cron is doing:
shell
1docker service logs --tail 20 wp_cronYou'll see lines like Executed the cron event 'wp_scheduled_delete' and Success: Executed a total of 7 cron events. The same pattern works for any PHP app: one replica of the app image running your scheduler, such as php artisan schedule:work for Laravel.
The database and other single points of failure
This setup scales the stateless part: NGINX and PHP. Three components are still single instances:
- MariaDB. For production, use a managed database (Amazon RDS, Cloud SQL, Azure Database or DigitalOcean Managed Databases). Remove the
dbservice and pointWORDPRESS_DB_HOSTat the managed endpoint. - NFS. If the NFS server goes down, uploads stop working on every node. A managed NFS service (Amazon EFS, Google Filestore, Azure Files) removes the server you have to look after. For large media libraries, store uploads in object storage like S3 with an offload plugin and serve them through a CDN: then you don't need shared storage at all.
- Redis. If it restarts, users lose their sessions. A managed Redis or Valkey service solves that, and you can use the same Redis as an object cache to take load off the database.
Start with what hurts most. For most sites it's the database.
Running the same design on Kubernetes
If you're on Kubernetes or moving there, the design stays the same. Only the objects change:
- PHP and NGINX become Deployments. NGINX and PHP-FPM can also run as two containers in one Pod.
- The Swarm service name becomes a Kubernetes Service, and the load balancer becomes an Ingress or a Gateway.
- Scaling becomes a HorizontalPodAutoscaler, which adds PHP replicas by CPU or memory instead of a manual
docker service scale. - Uploads go to a
ReadWriteManyvolume, for example through the NFS CSI driver or your cloud's file storage driver. - Salts and the database password become Secrets, and cron becomes a CronJob.
Wrapping up
Scaling PHP across several Docker nodes is mostly about moving state out of the containers. Code goes into the image, uploads go to shared storage, sessions go to Redis, salts are the same everywhere, and cron runs in one place. After that, adding capacity is one docker service scale command, and adding a server is one docker swarm join.
New to Docker? Start with how to run a Docker container on your local machine and how to expose a port in a Docker container.
If you need help scaling a production setup like this or moving it to Kubernetes, our cloud engineering and Kubernetes consulting teams can help.